Advanced Payment Solutions takes an AI call prompter to pilot without an ML team
Advanced Payment Solutions has shown a case that is rare on the market: its voice AI assistant for calls was built not by ML engineers but by 12 backend developers. In six months the team brought the product to pilot. It skipped fine-tuning and a heavy vector database, moved generation to a local Qwen 8B, and reached a working latency of about two seconds, which is enough to give a manager hints in the middle of a conversation. The pilot has produced qualitative signals of usefulness, but no statistically significant conclusions on conversion or KPIs yet. The company says that would require scaling and seamless CRM integration.
AI-processed from Habr AI; edited by Hamidun News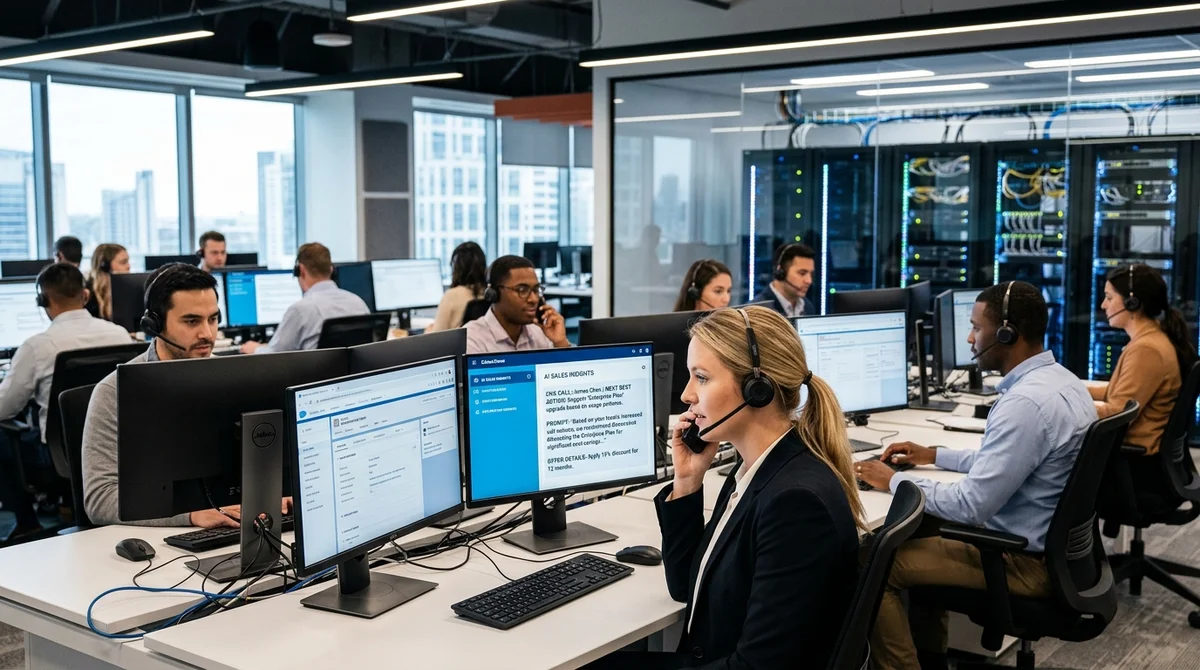
Advanced Payment Solutions has described how it took a voice AI call assistant to pilot without an in-house ML team. In six months, 12 backend developers built a system that tells a manager in real time how to answer a customer, with a latency of about two seconds.
How the MVP was built
Internally the project was called "Suflyor" ("Prompter"). Its job is to listen to an already transcribed conversation, work out which product is being discussed, spot a customer objection and immediately show the manager a text hint. The final stack was built on Python, FastAPI and PostgreSQL, with BERT classifiers and a local Qwen 8B handling classification and generation. For the business, it is a way to reduce the load on mentors and bring new employees up to their KPIs faster, especially when the ecosystem has more than 35 products and a manager has too many scenarios to keep in their head.
The key constraint was strict: the system has only 1.5–2 seconds to respond, otherwise a hint loses its value during a live conversation.
The team reached a working prototype quickly. In the first three weeks, the developers took text transcripts of calls, trained two BERT classifiers on roughly 1,500 dialogues, built simple knowledge bases with scripts and connected everything through prompts to a cloud GPT model. They built the interface in a day on Django. This proof of concept was slow, with a latency of 10–15 seconds, but it was enough to win the business over and get a green light for the MVP. After that came the engineering work of cutting latency, stabilizing the system and building integrations.
Why everything was simplified
At first the team, as often happens in AI projects, designed an overly ambitious system: its own audio pipeline, several complex classifiers, fine-tuning of a large language model, a vector database and even a self-learning loop. But it soon became clear that this path would stretch the launch to 12–18 months and sharply raise the chance of failure. Instead of trying to build the "perfect" architecture, the developers began systematically cutting everything the first release could do without.
"We did not fight the problems; we redesigned the system so that these
problems would not arise in it."
- They dropped fine-tuning in favor of RAG, to avoid spending months on labeling and to reduce the risk of hallucinations.
- They did not write their own transcription and used ready-made text segments from Voximplant.
- They simplified the objection classifier: instead of 15+ classes, they kept a binary scheme of "objection / no objection".
- They did not bring in a heavy vector database for a few megabytes of data and loaded structured JSON files straight into memory.
- They moved from cloud APIs to a local Qwen 8B on a GPU server, to meet the latency target and keep sensitive data inside the perimeter.
This set of trade-offs proved decisive. Cloud models responded in 7–20 seconds, and Qwen 32B, although it answered better, still missed the time budget. The more compact Qwen 8B turned out to be good enough for manager hints and stabilized latency at about two seconds. At the same time, local deployment settled the information security questions: call transcripts do not need to be sent to external services, so the team did not have to build a separate personal-data masking layer and pay for it with extra latency.
What the pilot showed
The most underestimated problem turned out to be data, not models. The team took 200 calls, split them among 12 participants and quickly ran into the limits of manual labeling: to classify objections correctly, it is not enough to pick out a phrase; you need to understand the context of the conversation and the logic of sales. As a result, the developers reframed the task itself. Instead of trying to "teach AI to think like an expert", they focused on a narrower goal: detect in time the moment when a manager needs help, then pull up the right script and generate a hint.
In the pilot, the system reached an average latency of about two seconds, rising to three in only 2–3% of cases. Service classification reached accuracy above 70%, and speech recognition reached 92% or better, depending on connection quality.
The team writes that the pilot has already had a qualitative effect: the first signals have appeared on convenience, reduced load on mentors and overall usefulness for operators. But there are no statistically significant conclusions on conversion and KPIs yet. For that, the product needs scaling and seamless integration directly into the CRM.
What this means
This case shows that an internal AI product does not always require a ready-made ML team from scratch. If a company has strong backend engineers, a clear business pain point and access to the processes, an MVP can be built faster by simplifying the architecture hard and dropping unnecessary "smart" components. The main takeaway is not the choice of a particular model but discipline: solve the business problem first, then check the constraints on speed and security, and only then make the stack more complex.
- Nov 2, 2026DeepSeek open-sources Super-agent prototype: p95 task completion time of 15.7 minutes vs. 29.5
- Nov 2, 2026TensorFold 1.2.0 boosts Qwen3.8-27B throughput on M3 Ultra by 44.2% at 16 streams
- Nov 1, 2026Adobe's EditAgent judge picks a usable edit 81.3% of the time, versus 74.8% for EditScore
- Nov 1, 202616 models tested on 7 search tools: Exa averaged 10.5 out of 14, SearXNG about 3
Key Questions Answered
How the MVP was built?
Internally the project was called "Suflyor" ("Prompter"). Its job is to listen to an already transcribed conversation, work out which product is being discussed, spot a customer objection and immediately show the manager a text hint. The final stack was built on Python, FastAPI and PostgreSQL, with BERT classifiers and a local Qwen 8B handling classification and generation. For the business, it is a way to reduce the load on mentors and bring new employees up to their KPIs faster, especially when the ecosystem has more than 35 products and a manager has too many scenarios t
Why everything was simplified?
At first the team, as often happens in AI projects, designed an overly ambitious system: its own audio pipeline, several complex classifiers, fine-tuning of a large language model, a vector database and even a self-learning loop. But it soon became clear that this path would stretch the launch to 12–18 months and sharply raise the chance of failure. Instead of trying to build the "perfect" architecture, the developers began systematically cutting everything the first release could do without. "We did not fight the problems; we redesigned the system so that these problems wo
What the pilot showed?
The most underestimated problem turned out to be data, not models. The team took 200 calls, split them among 12 participants and quickly ran into the limits of manual labeling: to classify objections correctly, it is not enough to pick out a phrase; you need to understand the context of the conversation and the logic of sales. As a result, the developers reframed the task itself. Instead of trying to "teach AI to think like an expert", they focused on a narrower goal: detect in time the moment when a manager needs help, then pull up the right script and generate a hint. In
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.