Habr AI walks through gradient descent in C++ and CUDA by training a model on MNIST
Habr AI has published part four of its "From MNIST to Transformer" series, this time on gradient descent and actually training a model on MNIST. The author shows how to build a training loop in C++ and CUDA without PyTorch, working through GPU memory, weight updates and error computation. The result is not an overview but a step-by-step walkthrough of how a neural network really learns.
AI-processed from Habr AI; edited by Hamidun News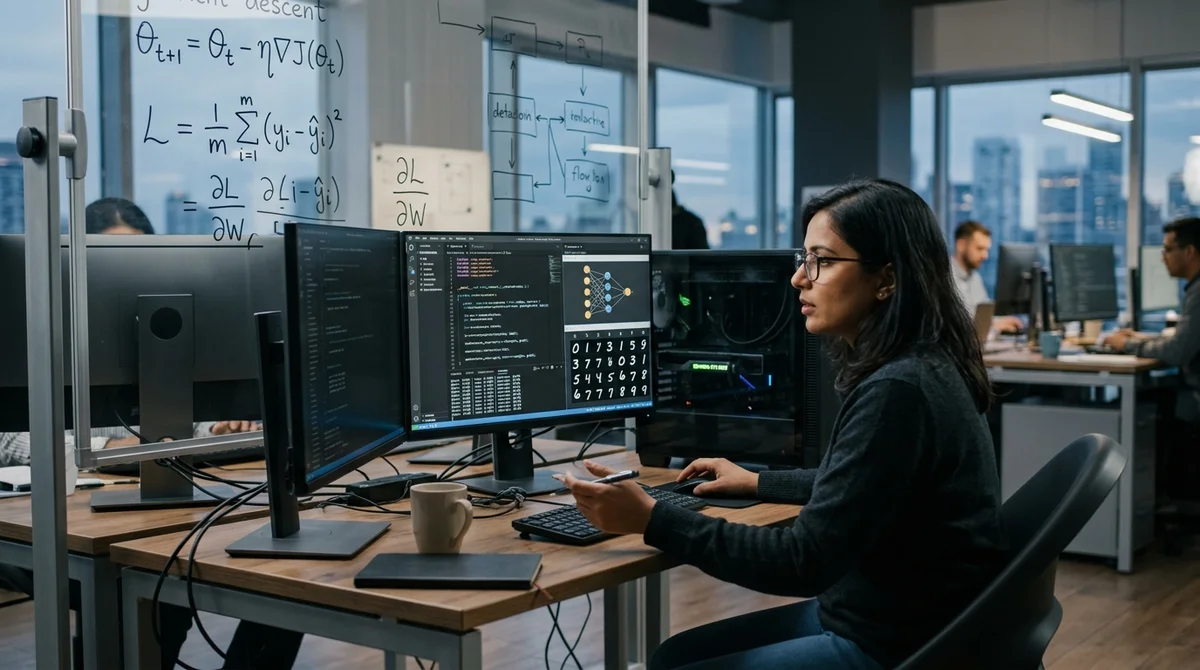
Habr AI has published part four of its "From MNIST to Transformer" series. This time the author moves to the most hands-on stage: training a model with gradient descent. The article shows how to build a basic training loop in C++ and CUDA without PyTorch and bring the model to the point where it recognizes handwritten digits.
What this part covers
The series is laid out as a route from minimal examples to the internals of modern neural networks. Instead of off-the-shelf frameworks, the author works through the low level step by step: CUDA kernels, memory, GPU computation and the math that drives all of it. In part four the focus shifts to gradient descent, the mechanism without which a model does not learn and simply makes random predictions. It is an important step, because this is where scattered pieces of code turn into a full training process.
The main idea of the article is to remove the "black box" effect from familiar AI tools. When a developer works only through high-level libraries, weight updates, error computation and movement across the loss surface often stay hidden. Here the author proposes building everything by hand: understanding where the gradient comes from, how it affects the parameters, and why even a simple model demands careful handling of data and memory. For anyone who wants to understand the foundations of LLMs, this approach is more useful than yet another ready-made notebook.
How training works
At the center of the piece is a practical implementation of training a model on the MNIST dataset. The author does not stop at the gradient descent formula but ties the math to code: how the error is computed, how the weights are updated and how these operations fit into C++ and CUDA. As a result, the article works both as an explanation of the algorithm and as a step-by-step engineering guide to building your own training loop.
- breakdown of gradient descent mechanics without abstractions
- training a model to recognize MNIST digits
- implementation of the key steps in C++ and CUDA
- working with memory and computation on the GPU
- linking math, code and accelerator architecture
The emphasis on training as a chain of dependent decisions rather than a single formula is especially valuable. You have to organize data correctly, avoid losing performance on copies, understand the cost of each GPU operation and track how the model's parameters change from step to step. At this scale it becomes clear why modern ML frameworks are so complex inside: what they automate is not magic but an enormous amount of engineering routine.
Why go low level
For a broad audience MNIST may look too simple an example, but that is the point. On a compact task it is easier to see the basic principles that later scale up to more serious architectures, including the Transformer. Once you understand how the gradient is computed, how the weights are updated and how this runs on a GPU, many of the "magical" properties of large models stop seeming inexplicable. The article is, in effect, a reminder: the path to LLMs starts not with prompt engineering but with understanding the computational foundation.
"This is the only way to truly understand how LLMs work and what
stands behind them."
The material also fits the demand for engineering education around AI. The market is currently flooded with tools that deliver fast results but rarely explain the internals. The "From MNIST to Transformer" series does the opposite: it slows the process down and forces you to look at details, from how memory is organized to the logic of parameter updates. For students, ML engineers and backend developers who need to understand hardware limits, it is a useful format.
What this means
Interest in low-level AI development is growing: it is no longer enough for developers to simply call a model through an API. Material like this points to a shift toward a deeper understanding of how neural networks are trained, where C++, CUDA and math are once again key skills rather than electives.
- Nov 2, 2026TensorFold 1.2.0 boosts Qwen3.8-27B throughput on M3 Ultra by 44.2% at 16 streams
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Habr author fine-tunes YOLOv8l on dental X-rays and pushes mAP50 to 0.642
- Nov 1, 2026Voice bots built on LLMs turn to Jev, a fast classifier, for decisions in 200–500 ms
Key Questions Answered
What this part covers?
The series is laid out as a route from minimal examples to the internals of modern neural networks. Instead of off-the-shelf frameworks, the author works through the low level step by step: CUDA kernels, memory, GPU computation and the math that drives all of it. In part four the focus shifts to gradient descent, the mechanism without which a model does not learn and simply makes random predictions. It is an important step, because this is where scattered pieces of code turn into a full training process. The main idea of the article is to remove the "black box" effect from
How training works?
At the center of the piece is a practical implementation of training a model on the MNIST dataset. The author does not stop at the gradient descent formula but ties the math to code: how the error is computed, how the weights are updated and how these operations fit into C++ and CUDA. As a result, the article works both as an explanation of the algorithm and as a step-by-step engineering guide to building your own training loop. breakdown of gradient descent mechanics without abstractions training a model to recognize MNIST digits implementation of the key steps in C++ and
Why go low level?
For a broad audience MNIST may look too simple an example, but that is the point. On a compact task it is easier to see the basic principles that later scale up to more serious architectures, including the Transformer. Once you understand how the gradient is computed, how the weights are updated and how this runs on a GPU, many of the "magical" properties of large models stop seeming inexplicable. The article is, in effect, a reminder: the path to LLMs starts not with prompt engineering but with understanding the computational foundation. "This is the only way to truly unde
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.