Raft breaks down where MCP and Thin MCP add extra latency for AI agents
The Raft team examined where exactly AI agents lose speed when working through MCP. Their tests showed that MCP itself adds only about 10 ms in-process, while the bulk of the slowdown comes from the network, serialization and extra hops between services. Thin MCP simplifies the architecture but does not guarantee a speedup. The best results came from an asynchronous design and a more careful organization of backend services.
AI-processed from Habr AI; edited by Hamidun News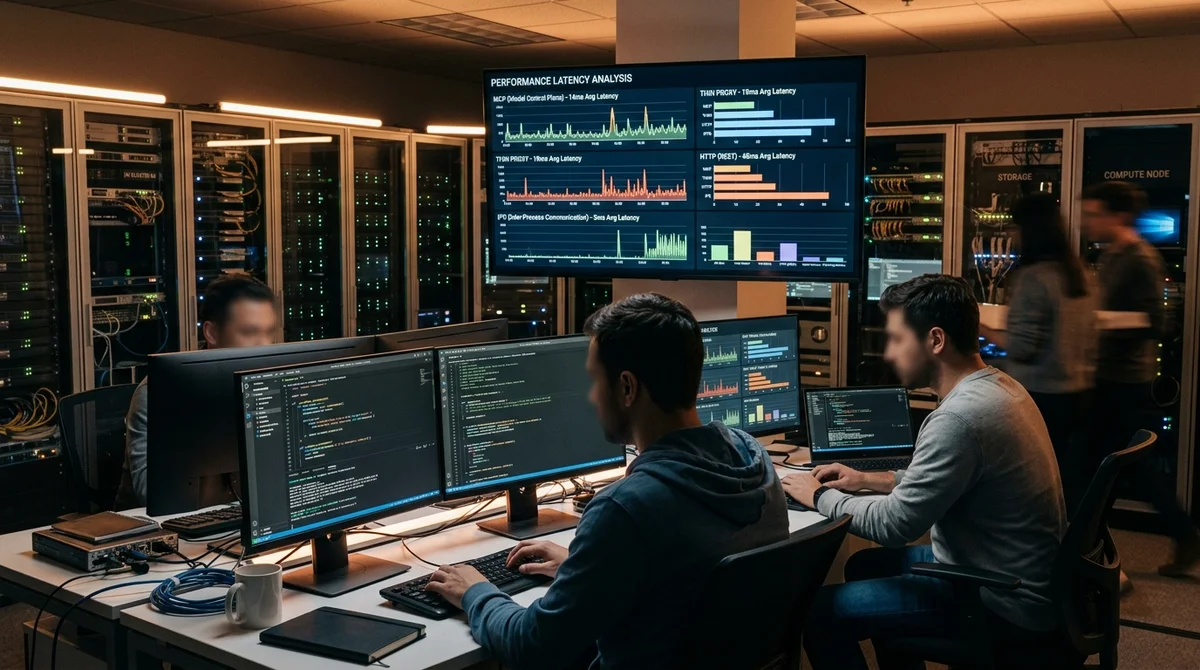
MCP is often pitched as a universal way to plug tools neatly into an LLM application, but in practice that modularity comes at the cost of latency. In a new analysis, Raft compared several architectures and showed that the problem usually lies not in one specific component but in how the entire request path from agent to tool and back is built.
Where latency comes from
The author started with a basic question: how much latency does MCP itself add if you remove the network and keep everything in one process? To find out, they compared a monolith without MCP against a monolith with in-process MCP. The pattern turned out to carry relatively little overhead: about 10–11 ms on average, occasionally up to 35 ms. That is an important baseline: if an agent stalls for hundreds of milliseconds, the culprit is usually not the use of MCP itself but the external layer around it.
The comparison then moved to a more realistic architecture in which MCP servers run in separate Docker containers. Here the picture changes noticeably: the average extra latency for the main tools rose to roughly 169 ms per call. Even so, traces showed that this is not the biggest consumer of time. The heaviest steps are fetching embeddings and running the reranker, while vector database search takes comparatively little. In other words, MCP adds a cost, but it is not always the main bottleneck in the chain.
What the tests showed
The article walks through several scenarios to separate the effects of transport, serialization and the runtime itself.
- S1, in-process MCP: about 10–11 ms of extra latency, so the runtime itself is relatively light.
- S2, separate MCP servers over a Docker network: about 169 ms of overhead per call on average, due to the network, serialization and inter-process communication.
- S3a, Thin MCP over HTTP + JSON: in one series of measurements overhead fell to about 128 ms, but the result was unstable and in repeated runs could be noticeably worse.
- S3b, Thin MCP over HTTP + YAML: latency rose to about 274 ms, pointing to the extra cost of serialization and deserialization.
- S4 and S5: ZeroMQ delivered about 200 ms, but with more predictable behavior, while a C++ runtime cut overhead to roughly 130–145 ms, without a radical change in order of magnitude.
The main takeaway from these numbers is that intuitive optimizations do not always work as you would expect. Replacing JSON with YAML did not speed up the system; it made it worse. Moving from HTTP to IPC was not an automatic win either: the iceoryx2 implementation did not show the expected gain, and only the ZeroMQ variant proved practically more useful, thanks to its asynchronous model. Even C++ helped only moderately, not dramatically.
Why thin does not save you
In the article, Thin MCP looks less like a magic speedup button and more like a way to simplify the architecture. In this design the proxy layer stays minimal and only translates calls, while business logic moves into separate HTTP services. This approach offers language independence, simplifies scaling and lets you write executors in Go, Rust or C++, even if no full MCP SDK exists for them yet.
Thin MCP is more an architectural tool than a way to optimize latency.
There is a practical catch: a thin approach may look faster in one run but fail to reproduce consistently in another. For a production system this is critical: sometimes predictable behavior under repeated load matters more than the best one-off p95. That is why Raft draws a fairly blunt but useful conclusion: to really speed up an AI agent, it is not enough to swap the language or protocol. You have to rebuild the interaction scheme between the proxy, backend components and heavy compute steps.
What this means
For teams building AI agents, this is a good antidote to superficial optimization. If a system is slow, first look at the number of hops between components, blocking operations, the concurrency model and heavy stages such as embeddings and reranking. Thin MCP can make a system cleaner and more flexible, and C++ or IPC can add some extra gain, but the decisive effect appears only when the architecture stops routing a request through unnecessary layers.
- Nov 2, 2026DeepSeek open-sources Super-agent prototype: p95 task completion time of 15.7 minutes vs. 29.5
- Nov 2, 2026Bun creator uses Claude Code to port 750K lines from Zig to Rust in 11 days
- Nov 2, 2026Microsoft releases 4B model Mage-VL-Cowork, which solves 66.0% of OSWorld-Verified tasks
- Nov 2, 2026Meta's Muse assistant keeps dossiers on loved ones and gets root on Ubuntu by default
Key Questions Answered
Where latency comes from?
The author started with a basic question: how much latency does MCP itself add if you remove the network and keep everything in one process? To find out, they compared a monolith without MCP against a monolith with in-process MCP. The pattern turned out to carry relatively little overhead: about 10–11 ms on average, occasionally up to 35 ms. That is an important baseline: if an agent stalls for hundreds of milliseconds, the culprit is usually not the use of MCP itself but the external layer around it. The comparison then moved to a more realistic architecture in which MCP s
What the tests showed?
The article walks through several scenarios to separate the effects of transport, serialization and the runtime itself. S1, in-process MCP: about 10–11 ms of extra latency, so the runtime itself is relatively light. S2, separate MCP servers over a Docker network: about 169 ms of overhead per call on average, due to the network, serialization and inter-process communication. S3a, Thin MCP over HTTP + JSON: in one series of measurements overhead fell to about 128 ms, but the result was unstable and in repeated runs could be noticeably worse. S3b, Thin MCP over HTTP + YAML: la
Why thin does not save you?
In the article, Thin MCP looks less like a magic speedup button and more like a way to simplify the architecture. In this design the proxy layer stays minimal and only translates calls, while business logic moves into separate HTTP services. This approach offers language independence, simplifies scaling and lets you write executors in Go, Rust or C++, even if no full MCP SDK exists for them yet. Thin MCP is more an architectural tool than a way to optimize latency. There is a practical catch: a thin approach may look faster in one run but fail to reproduce consistently in a
Build & Ship Production AI Agents Without Boilerplate Code
Start your free 72-hour trial at Hamidun Academy (academy.hamidun.com) — interactive lessons on Claude Code & Cursor, live Tech Radar, and production agent templates.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.