Claude Can't Save a Bad Brief: Why AI Delivers Convincing but Weak Results
A big prompt doesn't guarantee a good answer. Using Claude as an example, the author explains that AI more often produces plausible text than a genuinely useful result when the task hasn't been broken down in advance. The working minimum is four questions before you start: what you have as input, which stages are needed, what the output of each step should be, and what final acceptance looks like. The takeaway is blunt: AI amplifies a poorly defined task just as it amplifies a good one.
AI-processed from Habr AI; edited by Hamidun News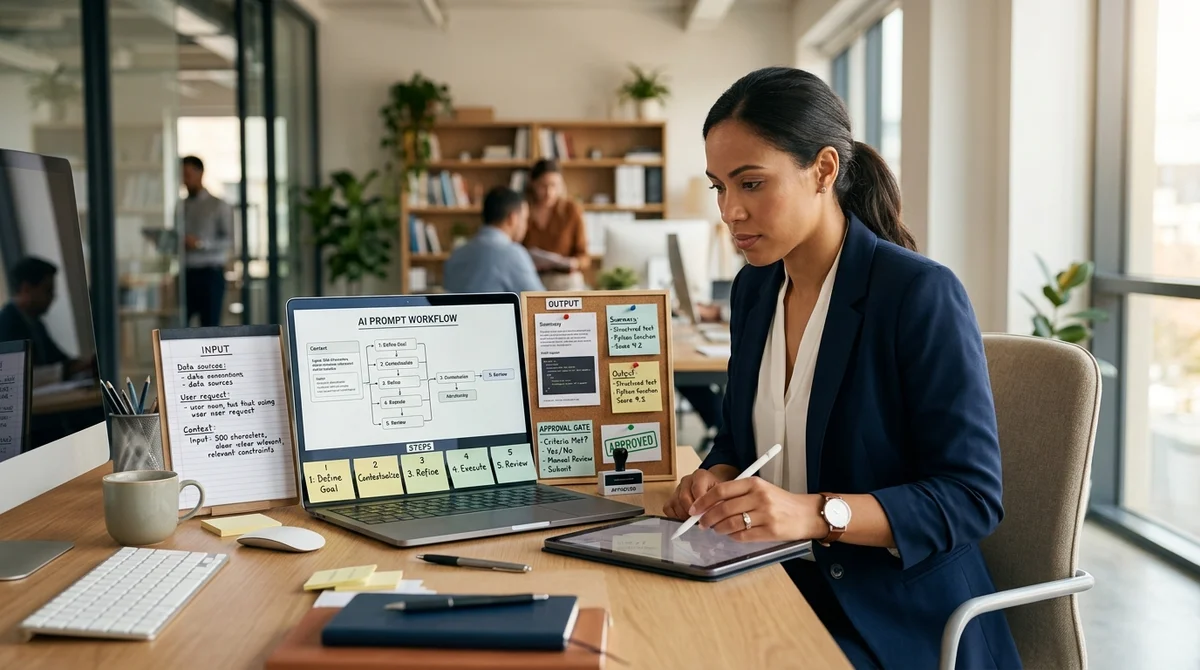
Big prompts, roles and incantations like think carefully do not guarantee a good answer from AI. Drawing on his work with Claude, the author examines why the model often speeds up the output of plausible text without reaching a useful result when the task itself is undefined.
Why this doesn't work
The core complaint is simple: AI rarely pushes back on a bad brief. A designer, analyst or developer would typically come back with clarifying questions, but a model more often fills in the missing context itself and delivers a confident answer. So the work feels fast, when in fact what accelerates is not the production of quality results but the production of text that looks convincing. Hence the fatigue after long iterations: you spend an hour rewriting something you should have gotten on the first or second try.
"A prompt is not a prayer."
The author ties this to a reversal in the cost of actions. Doing used to be expensive, while thinking and discussing were relatively cheap. Now AI produces five variants of an analysis, a letter or a strategy in seconds, while discussing the task with a team of several people becomes the most expensive part of the process. That creates the illusion that you can skip proper task definition and jump straight to generation. But a long prompt doesn't replace a clear goal, and magic formulas don't cure a lack of structure.
Four questions before the chat
Instead of hunting for the perfect wording, the author proposes returning to basic business-analysis discipline and building a map of the task before starting. Its logic rests on the As-Is, To-Be, Gap approach: what we have now, what the outcome should be, and what separates the two. This framework is useful not only for complex research but also for everyday tasks such as competitor analysis, outlining an article or reviewing user interviews. The point is to describe not a vague hope for a good answer but a concrete route to it.
- Input: which data, links, documents, hypotheses and observations you already have at the start.
- Stages: which actions the model should perform in order, without a vague "analyze."
- Output of each stage: what exactly should result from each step — a table, a list, a matrix, a draft.
- Final result: what the finished work looks like and by what criterion you will accept it without a "seems fine" feeling.
In practice this changes the format of working with the model. Instead of one huge prompt, it's better to build a pipeline of several steps with intermediate acceptance: first gather facts, then compare, then look for empty segments, and only then draw conclusions. In the competitor-analysis example, this approach turns an abstract request into a sequence of small tasks, where it's easier to catch an error earlier than in the final text.
How it's built in Claude
The author packaged this approach into a dedicated Claude skill for himself. It first checks what is actually needed: a one-off answer or a prompt for reuse. Then comes the As-Is, To-Be, Gap map, after which the system assesses how complete the request is across several mandatory elements — goal, audience, format, constraints and context. If data is missing, the model doesn't generate attractive text right away but asks clarifying questions.
The key step here is the Confirmation Gate: before working, the AI shows how it understood the task and waits for explicit confirmation. Next, the final prompt is assembled into a structured template following the Context, Role, Instructions, Style, Parameters scheme. The author separately stresses the importance of negative constraints, few-shot examples and targeted iteration on a specific error rather than on a "feels better" impression. If the result is too generic, you should fix not the mood of the request but the rule: add metrics, ban clichés, demand a clear response format. This mode moves prompting away from creative guesswork and toward engineering a process.
What this means
The main conclusion is harsh but useful: AI amplifies not only good decisions but also bad task definition. For teams, this is a signal to stop measuring effectiveness by the number of generated variants and start demanding a task map, intermediate acceptance and readiness criteria. The cheaper generation gets, the more expensive clear thinking becomes — and that is what now yields the biggest payoff.
- Nov 2, 2026LLM Agent Built a Gearbox in KOMPAS-3D, but Scored Only 50 out of 100 on the Specification
- Nov 2, 2026Agents ignored the prompt to read memory in 7 of 7 sessions: an analysis of 13 thousand logs
- Nov 2, 2026Karpathy Built HackerTube, a Catalog of 6,454 Videos, in Two Hours with Claude Code
- Nov 2, 2026We Audited 929 Automations at Alpina: What Corporate AI Training Should Look Like in 2026
Key Questions Answered
Why this doesn't work?
The core complaint is simple: AI rarely pushes back on a bad brief. A designer, analyst or developer would typically come back with clarifying questions, but a model more often fills in the missing context itself and delivers a confident answer. So the work feels fast, when in fact what accelerates is not the production of quality results but the production of text that looks convincing.
What are the key details on Four questions before the chat?
Instead of hunting for the perfect wording, the author proposes returning to basic business-analysis discipline and building a map of the task before starting. Its logic rests on the As-Is, To-Be, Gap approach: what we have now, what the outcome should be, and what separates the two. This framework is useful not only for complex research but also for everyday tasks such as competitor analysis, outlining an article or reviewing user interviews.
How it's built in Claude?
The author packaged this approach into a dedicated Claude skill for himself. It first checks what is actually needed: a one-off answer or a prompt for reuse. Then comes the As-Is, To-Be, Gap map, after which the system assesses how complete the request is across several mandatory elements — goal, audience, format, constraints and context. If data is missing, the model doesn't generate attractive text right away but asks clarifying questions.
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.