DeepSeek meets Gemma: a hybrid LLM experiment on Kaggle that broke the Transformers library
A Kaggle experiment tried something close to impossible: take the 31B weights of Gemma, transplant them into DeepSeek's MoE scaffold, and run the hybrid without any retraining. Getting there meant patching Transformers, working around an initialization failure on 4-bit weights, and hunting down hidden experts by hand. The resulting model talks incoherently, but the experiment shows how far you can push PyTorch, Hugging Face and a pile of hacks.
AI-processed from Habr AI; edited by Hamidun News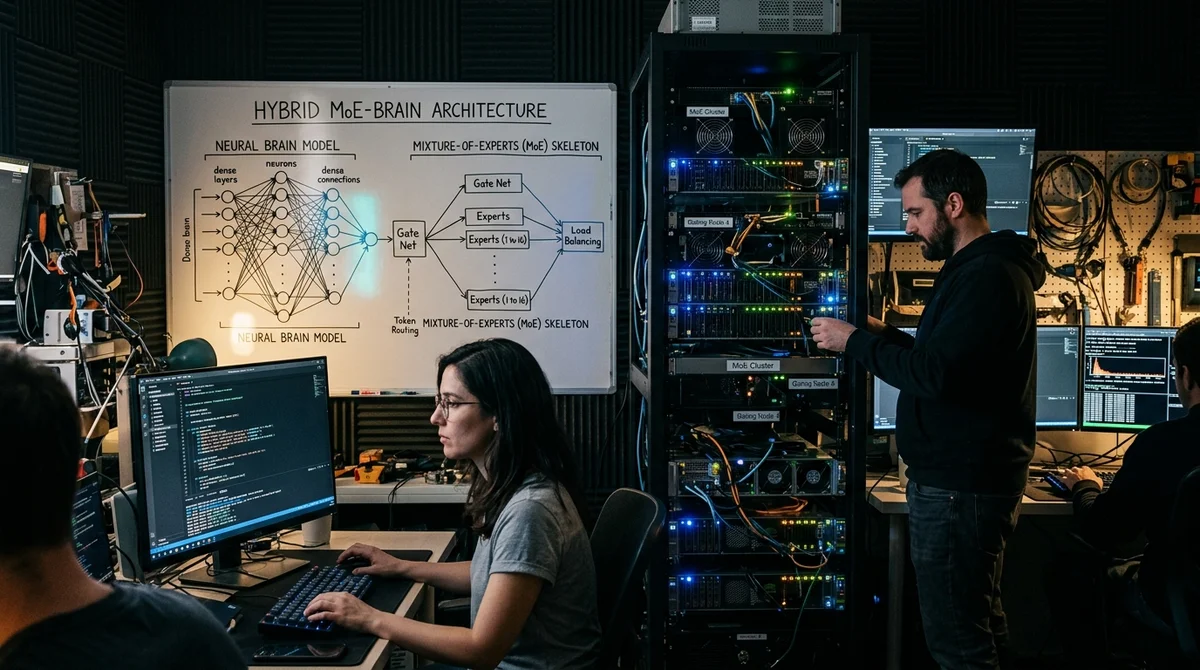
A group of hobbyists built a hybrid LLM that almost breaks the rules: they took four layers of the 31B Gemma model and built them into an empty DeepSeek-V4 MoE architecture without any retraining. It did not produce a working ChatGPT competitor, but the process showed how deeply PyTorch and Transformers can be bent out of shape to test an extreme idea.
Why build a hybrid
The idea grew out of very tight constraints: two free T4 GPUs on Kaggle, about 30 GB of RAM and no budget for full fine-tuning. Instead of training, the authors chose to test a cruder approach: structural splicing of models. The donor was Gemma-4-31B, compressed to the 4-bit NF4 format, and the "skeleton" was an empty DeepSeek-V4 with a Mixture-of-Experts router. The task sounded almost like a meme: move part of the weights from one architecture into another and see whether the chimera could be brought to life at all.
From an engineering standpoint, the project was interesting not for the quality of its output but for the fact of compatibility itself. Gemma and DeepSeek have different dimensions, their own normalization logic, different attention blocks and their own rules for routing tokens between experts. Textbooks usually treat such a transfer as impossible without intermediate projections and retraining. The authors deliberately broke that rule and set up an experiment in library survival: what would fail first, the model, Kaggle's memory or the Hugging Face stack itself.
Where it all fell apart
The first failure came at load time. Transformers refused to properly recognize the custom `gemma4` type, then crashed with a `dict.to_dict()` error, because one internal module serialized the config into a plain dictionary and immediately tried to treat it as an object. To get past this, the authors registered the type manually in `CONFIG_MAPPING` and added a monkey patch for `GenerationConfig` that wraps the dictionary in a proxy object on the fly. Without it, the whole operation ended before the hybrid was even created.
Next, the library tried to initialize the empty parts of DeepSeek with random noise by calling `normal_`. PyTorch then raised a `NotImplementedError`: the donor weights had been loaded through bitsandbytes in 4-bit form and stored as `uint8`, while the normal-distribution generator works on float tensors. The fix was as blunt as possible: the authors intercepted `TORCH_INIT_FUNCTIONS["normal_"]` and stopped it from touching byte tensors. It is not a pretty fix but a surgical workaround, and without it the transplant would not even start.
The most painful part turned out to be DeepSeek's experts and memory. The MoE blocks were hidden not in an ordinary `ModuleList` but inside a custom class that cannot simply be iterated over in a loop. On top of that, unpacking a 31B Gemma layer in Kaggle's RAM led to an almost instant OOM. To get around this, the authors wrote a recursive "sonar" that searches for the needed sublayers by the attributes `gate_proj`, `up_proj` and `down_proj`, and moved the weights in micro-batches through the CPU, spreading the models across two GPUs and calling the garbage collector constantly.
"In machine learning there are no impenetrable architectural walls."
How the model was stitched together
The final script boiled the whole operation down to a sequence of hard patches and weight copies. For each of the four layers, it fitted matrices to the size of the target layer, padding them with zeros where needed, transplanted the attention projections separately, and moved the MLP components separately for each expert it found. Memory was cleared right after every major copy. After the transplant, the authors also had to rewrite the MoE router so the model would not crash on dimension conflicts during inference and could produce at least some text.
The key technical steps were:
- Registering the custom Gemma config in Transformers' global registry
- A monkey patch for `GenerationConfig` that survives the `dict.to_dict()` error
- Blocking `normal_` for 4-bit `uint8` weights
- Recursive expert search and weight transfer in micro-batches through the CPU
Testing the resulting chimera gave the expected result: the model did start, but it generated incoherent text, a mix of random tokens and fragments of phrases. The authors still counted this as a success, because the goal was not answer quality but demonstrating the principle. They did not reconcile the vocabularies, train transitional projections or fine-tune after the transplant, so a chaotic stream of output tokens was almost inevitable. Still, the experiment showed that architectural limits often turn out to be not a wall but a long list of low-level problems that code can get around.
What this means
Such experiments do not produce a finished product, but they map the boundaries of current open-source LLMs well. If weights, quantization, routing and hidden states can be at least partly joined without retraining, that opens room for more practical hybrids, with proper projections, vocabulary adaptation and subsequent tuning. For developers it is a signal: the stack around models is still fragile, which means the space for unconventional builds is only growing.
- Nov 2, 2026DeepSeek open-sources Super-agent prototype: p95 task completion time of 15.7 minutes vs. 29.5
- Nov 1, 202616 models tested on 7 search tools: Exa averaged 10.5 out of 14, SearXNG about 3
- Nov 1, 2026MoneyGate safety layer blocked all 42 fraudulent requests to local AI models
- Oct 31, 2026DeepSeek-V4.1-Flash cuts HBM KV cache to 890 bytes per token, down from 3514
Key Questions Answered
Why build a hybrid?
The idea grew out of very tight constraints: two free T4 GPUs on Kaggle, about 30 GB of RAM and no budget for full fine-tuning. Instead of training, the authors chose to test a cruder approach: structural splicing of models. The donor was Gemma-4-31B, compressed to the 4-bit NF4 format, and the "skeleton" was an empty DeepSeek-V4 with a Mixture-of-Experts router. The task sounded almost like a meme: move part of the weights from one architecture into another and see whether the chimera could be brought to life at all. From an engineering standpoint, the project was interest
Where it all fell apart?
The first failure came at load time. Transformers refused to properly recognize the custom `gemma4` type, then crashed with a `dict.to_dict()` error, because one internal module serialized the config into a plain dictionary and immediately tried to treat it as an object. To get past this, the authors registered the type manually in `CONFIG_MAPPING` and added a monkey patch for `GenerationConfig` that wraps the dictionary in a proxy object on the fly. Without it, the whole operation ended before the hybrid was even created. Next, the library tried to initialize the empty par
How the model was stitched together?
The final script boiled the whole operation down to a sequence of hard patches and weight copies. For each of the four layers, it fitted matrices to the size of the target layer, padding them with zeros where needed, transplanted the attention projections separately, and moved the MLP components separately for each expert it found. Memory was cleared right after every major copy. After the transplant, the authors also had to rewrite the MoE router so the model would not crash on dimension conflicts during inference and could produce at least some text. The key technical ste
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.