VK unveils DataCopilot, a multi-agent system for corporate data and documentation
VK has unveiled DataCopilot, an internal AI assistant for working with its corporate data warehouse and documentation. The system grew out of an audit of real requests to the Data Office and data platform engineers. It helps find data marts, explains where things are stored, advises on access and can even prepare ETL scripts. Instead of a single RAG pipeline, the team chose a multi-agent architecture tailored to different types of tasks.
AI-processed from Habr AI; edited by Hamidun News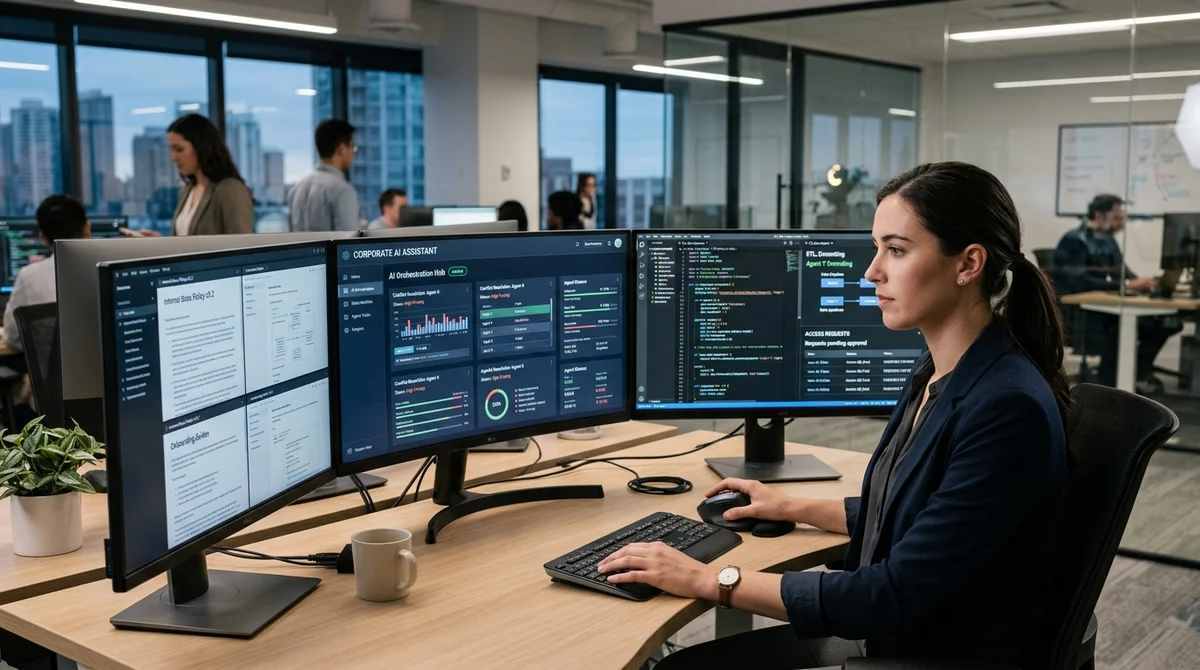
VK has detailed DataCopilot, an internal AI assistant for working with its corporate data warehouse and the related documentation. The project did not grow out of LLM fashion but from an analysis of real requests from analysts, managers and engineers who spend time every day on repetitive questions.
Where they started
The team did not start by picking a model or yet another RAG setup. First, VK looked at the routine around the Data Office and the data platform: which questions land in support, what people ask most often in chats, and where employees lose time hunting for the right data mart, a field description or the right approval process. The audit produced a clear list of tasks that can be automated without rebuilding the whole DWH and without trying to build a "universal intelligence" for every case at once.
From that list the team sketched the future assistant. It has to understand the data mart catalog, explain what is stored where, advise on corporate documentation, help with access and generate working drafts for ETL. In other words, this is not a chatbot for the sake of a chatbot, but an interface to the company's data and internal knowledge. For analysts and managers it saves time; for engineers it reduces the stream of repetitive requests.
Why not RAG
For some requests, classic RAG does work: the user asks a question, the system finds relevant documents and builds an answer from them. But in a corporate environment this quickly stops being enough. A single question may require moving between the data mart catalog, the description of specific tables, an access guide and a script template. If all of this goes through one chain without specialization, answer quality starts to fluctuate, and extra context only gets in the way.
That is why VK is betting on a multi-agent architecture, essentially a swarm of specialized helpers. One agent may handle search and interpretation of documentation, another navigation of the warehouse, a third code generation, a fourth access request procedures. Above them sits a coordinator that recognizes the type of request, picks a route and assembles the final answer. This approach matches the real structure of corporate data better, where sources, rules and actions differ greatly from one another.
What the system can do
According to the project description, DataCopilot is built as a practical working tool rather than a demonstration of model capabilities. It covers the points where an employee usually has to switch between support chats, the data catalog, internal instructions and their own drafts. The user gets either a short answer with the necessary context or a semi-finished artifact that can be quickly adapted to the task.
- Helps find the right data mart and understand what data it holds
- Explains where exactly information is stored and how it relates to other entities
- Advises how to file an access request without going to support
- Answers narrow questions about internal documentation and DWH working rules
- Writes scripts that can be taken into ETL processes and adapted to your own pipeline
The important point is that the system works at the junction of knowledge and action. It does not just retell documents but helps take the next step: prepare a query, draft the base of a script, shorten the path to the right table. That is usually what separates a useful corporate AI from yet another "smart search". Still, responsibility for the final use of the result remains with the human, especially when it comes to access, data migrations and code for production ETL processes.
What it means
The DataCopilot story shows where corporate AI is actually heading: not toward one all-knowing chatbot, but toward a set of narrow agents built around a specific working context. For teams that have a DWH, a data mart catalog, internal regulations and a stream of repetitive questions, this approach can deliver far more value than abstract RAG over all documents at once.
- Nov 2, 2026Karpathy builds a YouTube clone with 6454 videos from Hacker News recommendations in two hours
- Nov 2, 2026Karpathy used Claude to build HackerTube from 6,454 videos recommended on Hacker News
- Nov 2, 2026Arca gives AI agents finance tasks lasting up to 10 days, but leaves the trades to humans
- Nov 2, 2026DeepSeek open-sources Super-agent prototype: p95 task completion time of 15.7 minutes vs. 29.5
Key Questions Answered
Where they started?
The team did not start by picking a model or yet another RAG setup. First, VK looked at the routine around the Data Office and the data platform: which questions land in support, what people ask most often in chats, and where employees lose time hunting for the right data mart, a field description or the right approval process. The audit produced a clear list of tasks that can be automated without rebuilding the whole DWH and without trying to build a "universal intelligence" for every case at once. From that list the team sketched the future assistant. It has to understand
Why not RAG?
For some requests, classic RAG does work: the user asks a question, the system finds relevant documents and builds an answer from them. But in a corporate environment this quickly stops being enough. A single question may require moving between the data mart catalog, the description of specific tables, an access guide and a script template. If all of this goes through one chain without specialization, answer quality starts to fluctuate, and extra context only gets in the way. That is why VK is betting on a multi-agent architecture, essentially a swarm of specialized helpers
What the system can do?
According to the project description, DataCopilot is built as a practical working tool rather than a demonstration of model capabilities. It covers the points where an employee usually has to switch between support chats, the data catalog, internal instructions and their own drafts. The user gets either a short answer with the necessary context or a semi-finished artifact that can be quickly adapted to the task. Helps find the right data mart and understand what data it holds Explains where exactly information is stored and how it relates to other entities Advises how to fi
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.