NextFilm details a movie recommendation model: cold start, a taste vector and a GPT layer
The NextFilm project shows how to tackle cold start in movie recommendations without relying on genres alone. The system first collects starter ratings for films the user has already watched, then builds a taste vector from finer-grained features and checks it against MovieLens 25M patterns. Only after that does it use GPT for re-ranking, clearer results and short explanations of why each film was chosen.
AI-processed from Habr AI; edited by Hamidun News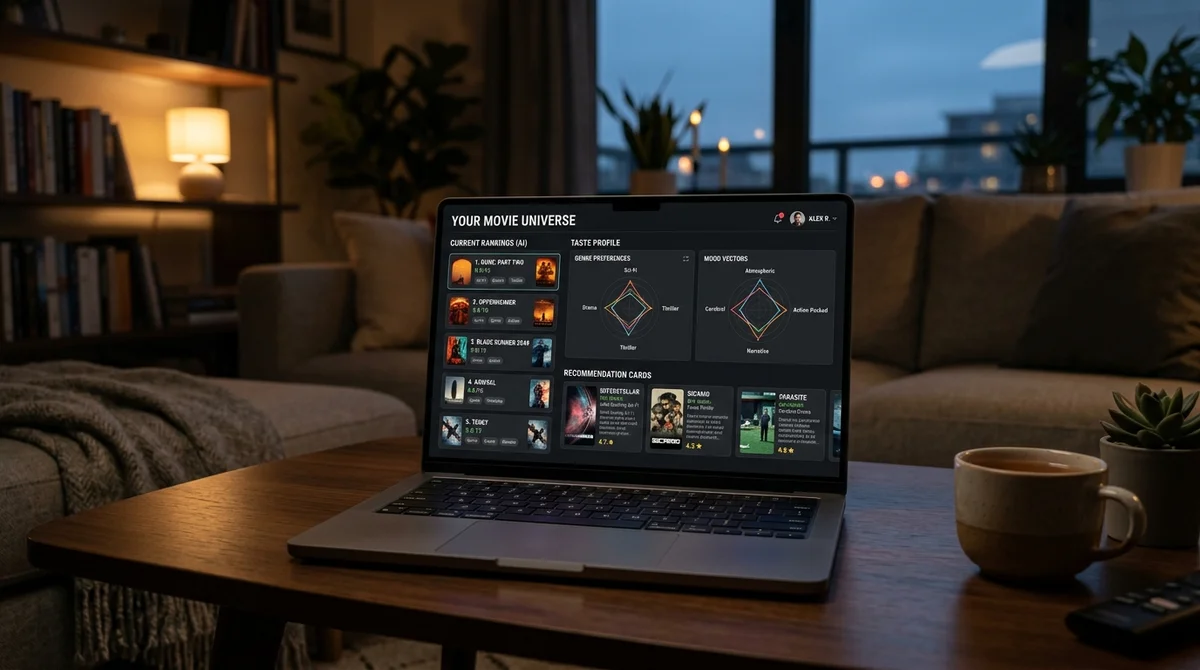
The author of NextFilm has described how they build a movie recommender for users about whom almost nothing is known at the start. Instead of simple genre lists, they propose a hybrid pipeline: gather the first signals, build a taste vector, check it against collective patterns, and only then bring in GPT.
Why genres are not enough
The problem starts with the fact that the same genre guarantees nothing. Two viewers may both love science fiction, but one wants slow, philosophical stories while the other wants a dense plot and spectacle. For a pair of viewers the task is harder still: the goal is not just a "popular film" but one that will not be a random pick for either of them.
That is why "what to watch tonight" lists work as a shop window but quickly break down as personal recommendations.
NextFilm's author starts not from genres but from real viewing experience. At the outset, the system needs to know what a person has already seen, what they rated highly, and what they have not watched at all. This is critical for cold start: without that distinction, the model easily confuses missing data with a negative reaction and draws conclusions from nothing. This context also determines how risky it is to suggest options that are too obvious or already watched.
The system must understand not only "what the user likes" but also
what viewing experience they have.
How the pipeline works
After the first ratings, the model moves from a list of watched films to a more precise profile. Taste is broken down into fine-grained features: pace, emotional tone, depth, spectacle, familiarity of form and plot density. This produces an internal preference vector that explains why two films from the same genre can be very far apart for a specific person. It gives the model a more explainable basis for its first accurate hypotheses.
- First, the user marks films already watched and gives initial ratings
- The system builds a starting profile and separates strong signals from noise
- Then a taste vector is formed from a set of features, not just genres
- Next, the model matches this profile against MovieLens 25M patterns
- After candidates are ranked, the results are refined for final presentation
A separate layer in the design is the collective signal. The author uses MovieLens 25M, which contains 25 million ratings across more than 62,000 films. The logic is simple: if a user likes a certain set of films, the system looks at what else people with similar patterns consistently like. This does not replace the personal profile; it makes recommendations more stable and reduces the share of chance matches. This is how a hybrid design gains scale without fully losing personalization.
Where GPT comes in
GPT does not replace the recommender itself. It kicks in after signal collection, profile building and baseline ranking. Its role is to reorder candidates, group the results and explain to the user why the selection looks the way it does. This matters because an LLM can improve how the results are perceived, but it will not fix weak baseline relevance if the ranking was poorly built to begin with. In effect, it handles the packaging of the result, not its origin.
The design has limitations. The most sensitive point is onboarding: for recommendations to become useful, a new user has to spend time on starter ratings. There is also a risk of drifting toward overly popular films if collective data starts to dominate the personal profile. In addition, tastes change over time, so the model needs to be retrained on new signals rather than treating the profile as fixed after the first login. Without updates, the system will quickly start repeating itself and lose accuracy.
What this means
The NextFilm story shows well how the role of LLMs in recommendation products is changing. The main value still comes from data, ranking and careful handling of cold start, while GPT becomes not "magic" but an interface and interpretation layer. For media services, this is a practical guideline: build the signal first, then add a generative layer on top. The approach can be useful not only for movie services but for any product where recommendations have to be explained to the user.
Key Questions Answered
Why genres are not enough?
The problem starts with the fact that the same genre guarantees nothing. Two viewers may both love science fiction, but one wants slow, philosophical stories while the other wants a dense plot and spectacle. For a pair of viewers the task is harder still: the goal is not just a "popular film" but one that will not be a random pick for either of them. That is why "what to watch tonight" lists work as a shop window but quickly break down as personal recommendations. NextFilm's author starts not from genres but from real viewing experience. At the outset, the system needs to k
How the pipeline works?
After the first ratings, the model moves from a list of watched films to a more precise profile. Taste is broken down into fine-grained features: pace, emotional tone, depth, spectacle, familiarity of form and plot density. This produces an internal preference vector that explains why two films from the same genre can be very far apart for a specific person. It gives the model a more explainable basis for its first accurate hypotheses. First, the user marks films already watched and gives initial ratings The system builds a starting profile and separates strong signals from
Where GPT comes in?
GPT does not replace the recommender itself. It kicks in after signal collection, profile building and baseline ranking. Its role is to reorder candidates, group the results and explain to the user why the selection looks the way it does. This matters because an LLM can improve how the results are perceived, but it will not fix weak baseline relevance if the ranking was poorly built to begin with. In effect, it handles the packaging of the result, not its origin. The design has limitations. The most sensitive point is onboarding: for recommendations to become useful, a new
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.