VectifyAI's PageIndex offers embedding-free retrieval for long documents
VectifyAI's PageIndex takes a different approach to long documents: instead of chunks and a vector database, it builds a hierarchical table of contents with summaries and hands the LLM only the pages it needs. The idea works well for financial, legal, and technical PDFs, but the accuracy comes at a price: more tokens, slower responses, and weak scalability across large document collections.
AI-processed from Habr AI; edited by Hamidun News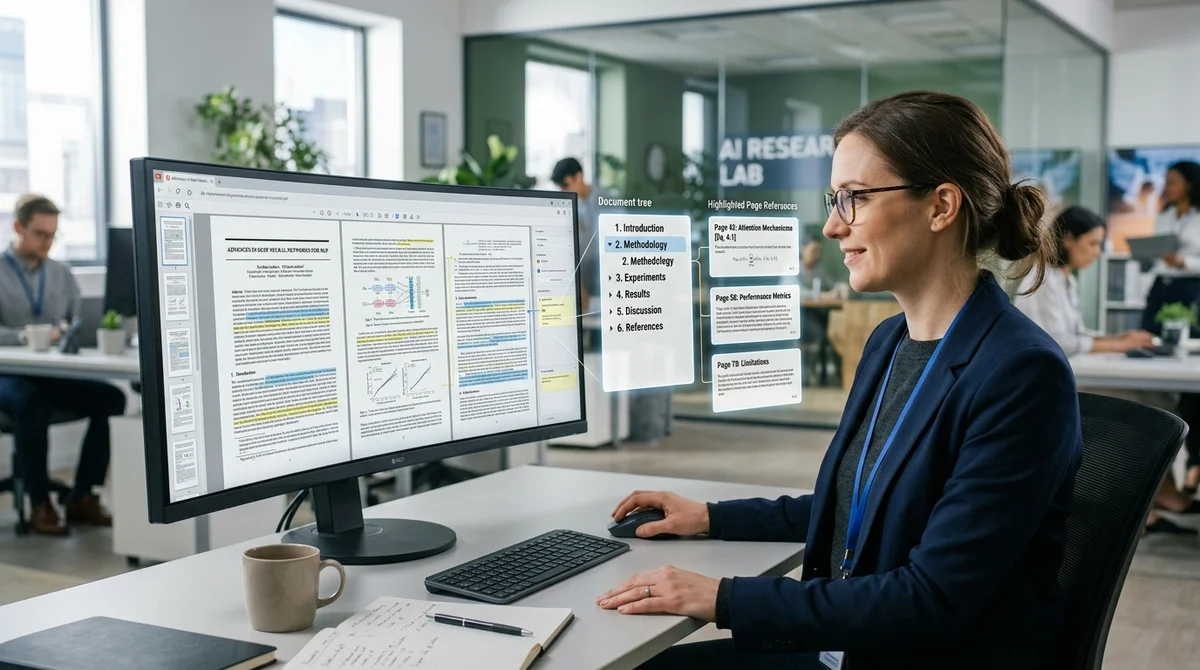
PageIndex is one of the most visible new contenders for the title of "RAG without a vector database." Instead of the familiar embeddings-and-chunks setup, it builds a hierarchical table of contents for a document, with short descriptions of each section, and then asks an LLM to reason its way to the relevant nodes and their pages. The approach feels fresh, and for long, well-structured PDFs it really can work closer to the way a person reads a document.
How PageIndex works
The mechanics are fairly simple. The document is first split into pages, and then the model and supporting code assemble an extended TOC: a tree of sections with titles, page ranges, and a summary for each node. When a question comes in, the prompt gets neither the whole document nor a set of arbitrary text fragments, but this structure. The LLM picks the relevant branches of the tree, and only the pages tied to them go into the final request. The system works without embeddings, without a vector store, and without artificial chunking, which often breaks meaning at fragment boundaries.
Why the project is drawing interest
That is exactly why PageIndex is getting so much attention. For long financial reports, legal documents, technical manuals, and educational materials, the approach feels natural: people usually start with the table of contents too, rather than sifting through text piece by piece. In the project's repository, VectifyAI's developers explicitly pitch the system as reasoning-based retrieval and claim it helped reach 98.7% accuracy on FinanceBench. For teams working with a single large document or a small collection of complex PDFs, that sounds like a strong alternative to a conventional RAG pipeline, especially if they want more interpretable retrieval with clear references to sections and pages.
Where the approach hits its limits
The real question, though, is not whether PageIndex can replace vector search, but where this approach runs out of road. The criticism here is fairly down-to-earth. First, the TOC also has to be stored somewhere, especially when there is more than one document, so the "completely index-free" pitch is a bit disingenuous.
Second, there is no convincing strategy yet for selecting documents in large collections: metadata, keyword search, TF-IDF, and BM25 are not going anywhere and often remain a cheap first-pass filter. Third, reasoning retrieval is almost inevitably more expensive in tokens and slower to respond. If a good vector RAG setup already delivers around 90% quality, the extra points of accuracy can cost several times more, and that is not a sensible trade for every product.
Practical limitations and getting started
Hands-on experience reveals limits too. One review notes that PageIndex handled fiction without explicit structure poorly: if a document has no sections or headings, there is simply nothing to build a "smart table of contents" from. Results on academic text were better, because it has a proper section hierarchy.
You can run the system locally from the open repository: install the dependencies, set an API key for a compatible LLM via LiteLLM, and run a PDF or markdown file through run_pageindex.py. There are caveats here as well: the author specifically warns about the LiteLLM version, advises against installing the cloud pageindex package from pip for local use, and reports that tree quality drops noticeably with weak local models, while the process itself can take tens of minutes even on a relatively small document.
What this means in practice
What does this mean in practice? PageIndex does not look like a vector search killer, but it does look like a useful new layer in RAG architecture. It makes the most sense not as a direct replacement, but as a specialized tool for long, structured documents where explainability, precise navigation, and page-level work matter. The most realistic scenario is hybrid: a cheap metadata or vector search first, then PageIndex to pinpoint the right sections. That compromise better reflects reality: no universal replacement for vector RAG has emerged yet, but document-first approaches like PageIndex already have a clear niche of their own.
In short:
- VectifyAI's PageIndex is "RAG without a vector database": it builds a hierarchical table of contents and asks an LLM to pick the relevant nodes and pages.
- The system works without embeddings or chunking; the developers claim 98.7% accuracy on FinanceBench.
- It is more realistic to treat PageIndex as a layer for long, structured documents in a hybrid setup than as a replacement for vector RAG.
- Nov 2, 2026EDU-Jev 4B grades student work with 67.6% accuracy, beating commercial APIs by 9.4 points
- Oct 28, 2026Anthropic reveals how it builds Claude with Claude: the brain separate from the hands
- Oct 28, 2026Bayer Launches Multi-Agent Engine on AgentCore: 80% of Questions Handled Without Engineers
- Oct 28, 2026Liquid AI releases LFM2.5-24B-A2B: an agent model with 2B active parameters
Key Questions Answered
How PageIndex works?
The mechanics are fairly simple. The document is first split into pages, and then the model and supporting code assemble an extended TOC: a tree of sections with titles, page ranges, and a summary for each node. When a question comes in, the prompt gets neither the whole document nor a set of arbitrary text fragments, but this structure. The LLM picks the relevant branches of the tree, and only the pages tied to them go into the final request. The system works without embeddings, without a vector store, and without artificial chunking, which often breaks meaning at fragment
Why the project is drawing interest?
That is exactly why PageIndex is getting so much attention. For long financial reports, legal documents, technical manuals, and educational materials, the approach feels natural: people usually start with the table of contents too, rather than sifting through text piece by piece. In the project's repository, VectifyAI's developers explicitly pitch the system as reasoning-based retrieval and claim it helped reach 98.7% accuracy on FinanceBench. For teams working with a single large document or a small collection of complex PDFs, that sounds like a strong alternative to a con
Where the approach hits its limits?
The real question, though, is not whether PageIndex can replace vector search, but where this approach runs out of road. The criticism here is fairly down-to-earth. First, the TOC also has to be stored somewhere, especially when there is more than one document, so the "completely index-free" pitch is a bit disingenuous. Second, there is no convincing strategy yet for selecting documents in large collections: metadata, keyword search, TF-IDF, and BM25 are not going anywhere and often remain a cheap first-pass filter. Third, reasoning retrieval is almost inevitably more expen
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.