How TGS and AWS cut training of a seismic AI model from six months to five days
TGS, working with AWS, has cut the training time of its seismic foundation model from six months to five days. The company set up distributed training on SageMaker HyperPod, achieved near-linear scaling across 128 GPUs and expanded the 3D context the model analyzes by a factor of 4.5. That lets TGS refresh its models faster, see large geological structures more accurately and deliver improvements to customers more often.
AI-processed from AWS Machine Learning Blog; edited by Hamidun News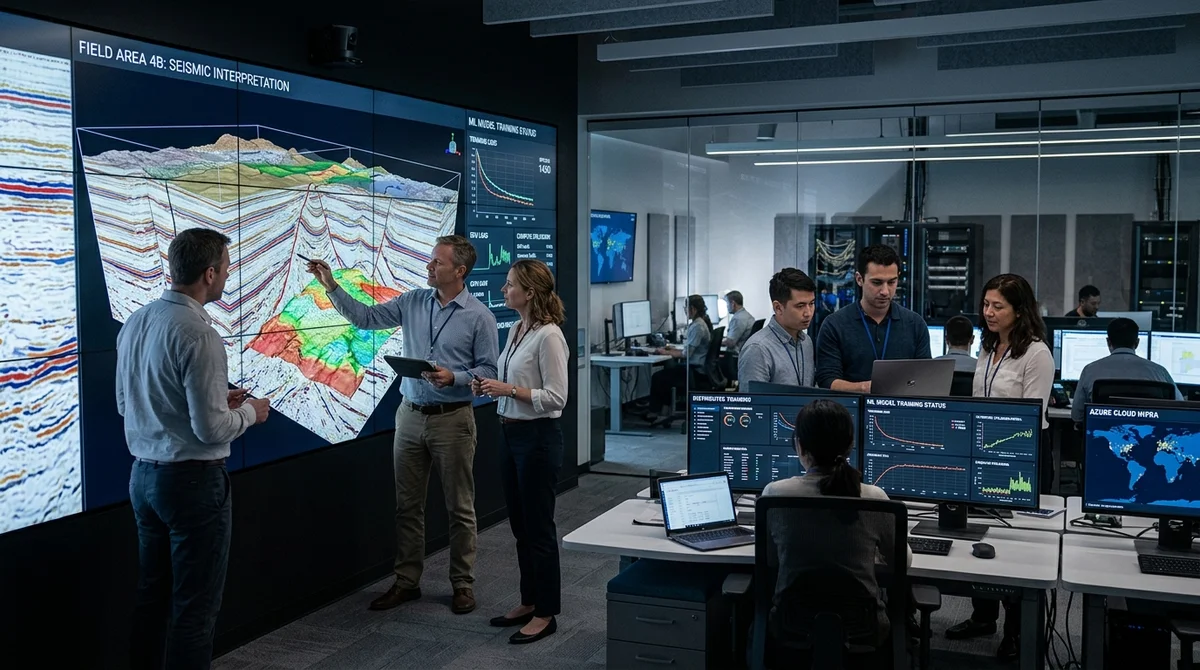
TGS, together with AWS, has posted a result that is rare for large AI projects: training of a seismic foundation model that used to take about six months now takes five days. At the same time, the team enlarged the context window, meaning the volume of three-dimensional geological data the model can analyze in a single pass. For companies working in subsurface exploration, that means faster iteration and a fuller picture of underground structures.
TGS is a geoscience data provider for the energy sector. The company uses seismic foundation models to analyze complex 3D datasets and find geological structures that matter for exploration and production. The model's base architecture is built on Vision Transformer and the Masked AutoEncoder training scheme. The main difficulty is not only the size of the model itself but the nature of the data: seismic volumes consist of billions of points, are stored in specialized formats and must be fed to GPUs continuously, without idle time.
Working with the AWS Generative AI Innovation Center, the company moved training to Amazon SageMaker HyperPod and built a cluster of 16 Amazon EC2 P5 nodes. Each node had 8 NVIDIA H200 GPUs with 141 GB of HBM3e memory, 192 vCPUs, 2 TB of RAM and EFAv3 networking at 3,200 Gbit/s. In total, that is 128 GPUs. According to AWS, this configuration delivered near-linear scaling: parallel efficiency held at roughly 90–95% as the cluster grew from one node to 16.
The data pipeline got separate attention. Instead of the classic setup with Amazon FSx for Lustre, the team chose direct streaming from Amazon S3. The reason is simple: as the cluster grows, S3 lets each node add its own throughput, whereas a shared file system becomes a bottleneck faster. TGS's training dataset is stored in MDIO, a format the company developed on top of Zarr and optimized for large scientific data in the cloud. After tuning multithreaded loading and prefetching, each node consistently received 4–5 GB/s, and the whole cluster 64–80 GB/s. This also cut storage infrastructure costs by more than 90%.
For distributed training, the team compared several approaches: DeepSpeed ZeRO-2, ZeRO-3 and FSDP2. ZeRO-2 offered the best balance of speed and memory savings: 1,974 samples per second versus 1,833 for FSDP2 and 869 for ZeRO-3. This matters because in such workloads maximum memory savings do not always produce the best overall result: if communication between GPUs becomes too expensive, throughput drops sharply. In this project, the team bet not on the theoretically most compact option but on the configuration that actually runs training faster in a production scenario.
The second key achievement involves expanding the context window. For seismic models, this directly affects the quality of analysis: the more rock volume the model sees in one pass, the better it captures both local details, such as small fractures, and large patterns, such as fault systems at the scale of an entire basin. Through context parallelism and an adaptation of ring attention to the ViT architecture for 3D data, the maximum input size grew from 640 x 640 x 1,024 to 1,536 x 1,536 x 2,048 voxels. Context length rose from 102,400 to 1.17 million tokens, and the analyzed volume grew roughly 4.5 times.
The practical upshot is that TGS can now update its models effectively every week rather than once every six months, bring in new geological data faster and give customers a broader analytical context. For AWS, it is another telling example that specialized foundation models in science and industry depend not only on model architecture but also on getting data, networking and distributed training right. For the market as a whole, the signal is clear: narrowly specialized AI is starting to win where long compute cycles and overly expensive infrastructure used to dominate.
- Oct 31, 2026Worldwide Express hands disputed invoices to AI agents and cuts unresolved disputes by 75%
- Oct 30, 2026AWS gives coding agents a live site preview straight from an isolated session
- Oct 30, 2026MoEngage Opens 400 Private APIs to AI Agents Through AgentCore Gateway, Without Building Its Own MCP Servers
- Oct 29, 2026NVIDIA Nemotron 3.5 Super VL: 120B Parameters, 12B Active, Running on AWS
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.