MarkTechPost shows how to build a lightweight VLA agent with a latent world model and MPC
MarkTechPost has published a hands-on tutorial on building a lightweight, VLA-style embodied agent. Instead of symbolic coordinates, the agent in the example sees RGB frames, learns a compact world model, and picks actions using model predictive control. It's a solid walkthrough for anyone who wants to understand how perception, prediction, and replanning fit together without a heavyweight stack.
AI-processed from MarkTechPost; edited by Hamidun News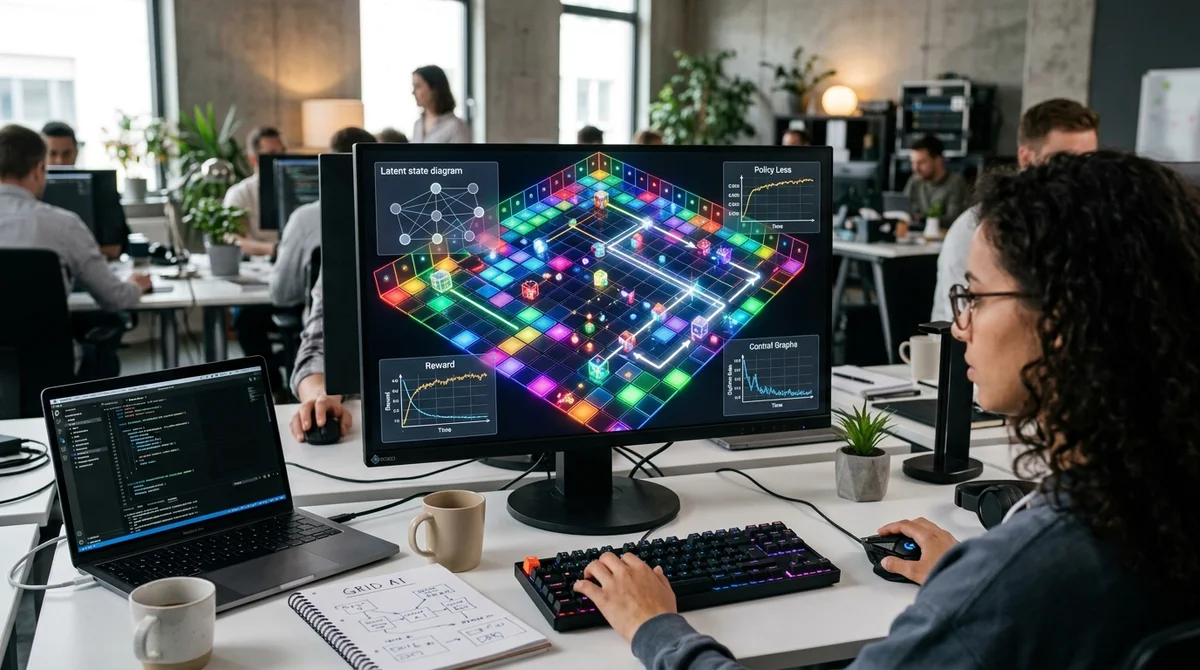
MarkTechPost has published a detailed tutorial on building a compact embodied agent that perceives its environment through images, builds an internal world model, and plans actions using model predictive control. The focus isn't a production-ready robot but a simulation that makes it easy to see how a loop of perception, prediction, planning, and replanning grows out of raw pixels. That format is especially valuable right now: Vision-Language-Action systems generate plenty of noise, but short, transparent examples that show how these ideas work at the architectural level are scarce.
The example is built on a grid world rendered entirely in NumPy. Instead of symbolic state variables such as the agent's coordinates or an obstacle map, the system receives ordinary RGB frames. That brings the task closer to real embodied scenarios, where an agent can't simply read a perfect description of the world and has to extract structure from a visual stream.
Even in a simple environment, this shift changes the problem itself: the model now has to figure out what it's looking at before it can choose an action. As a result, the tutorial clearly shows how pixel-based agents differ from classical systems that operate on a pre-prepared environment state. It also gives readers a convenient entry point: you can trace the whole path from input frame to output decision without complex math or bulky infrastructure.
The next layer is a lightweight latent world model. The observation is first encoded into a compact internal representation, and the model then learns to predict how that state will change in response to a chosen command. This lets the agent plan not in pixel space, which is too bulky and noisy, but in a more compressed latent space.
In practice, the agent can quickly roll out several possible future trajectories and compare them without brute-forcing images frame by frame. This is where the core idea of a world model becomes clear: the system first learns to internally "imagine" how the environment will evolve, then uses that imagination to choose its next step. The approach also makes the agent's behavior more interpretable: an engineer can separately inspect encoding quality, dynamics prediction accuracy, and the final planning.
For action selection itself, the authors bring in model predictive control, or MPC. The logic is simple: the agent doesn't commit to one long plan up front. At each step, it evaluates several candidates, forecasts their consequences through the world model, and picks the best short-horizon scenario. After each new observation, it recomputes, so behavior can be adjusted as the situation changes. The result is a simplified but highly illustrative loop of perception, prediction, and replanning.
The practical value of the piece is that it breaks embodied AI down into understandable building blocks without heavy simulators, robotics frameworks, or large multimodal models. That's especially useful for researchers, students, and engineers who want to do more than run ready-made demos and actually understand how perception, world modeling, and control connect within a single system. The authors are also upfront about the approach's limitations: this is a teaching environment, not a finished system for the physical world, and that's exactly why the architectural logic, which can later be carried over to more complex scenarios, is so easy to see.
The main takeaway from MarkTechPost's walkthrough is simple: you can understand embodied agents without a giant stack if you build a small but honest system where visual perception, a latent world model, and MPC work together. For engineers, it's a useful way to quickly test the basic ideas of world modeling and planning. For the AI market, it's another reminder that progress in agentic systems depends not only on model size but also on how well models can predict their environment and make decisions in a closed loop.
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Adobe's EditAgent judge picks a usable edit 81.3% of the time, versus 74.8% for EditScore
- Nov 1, 202616 models tested on 7 search tools: Exa averaged 10.5 out of 14, SearXNG about 3
- Nov 1, 2026Google's StreamVibe video agent beats other models by 10.7% on response timing and quality
Build & Ship Production AI Agents Without Boilerplate Code
Start your free 72-hour trial at Hamidun Academy (academy.hamidun.com) — interactive lessons on Claude Code & Cursor, live Tech Radar, and production agent templates.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.