NVIDIA shows a full model-optimization pipeline with FastNAS pruning and fine-tuning
NVIDIA has published a step-by-step guide to Model Optimizer that builds a complete model-optimization cycle in Google Colab: training ResNet20 on CIFAR-10, FastNAS pruning to a 60 million FLOPs limit, and then fine-tuning. The guide is useful because it shows not an isolated trick but a reproducible engineering pipeline, with checkpoints saved, the pruned model restored, and accuracy compared before and after compression.
AI-processed from MarkTechPost; edited by Hamidun News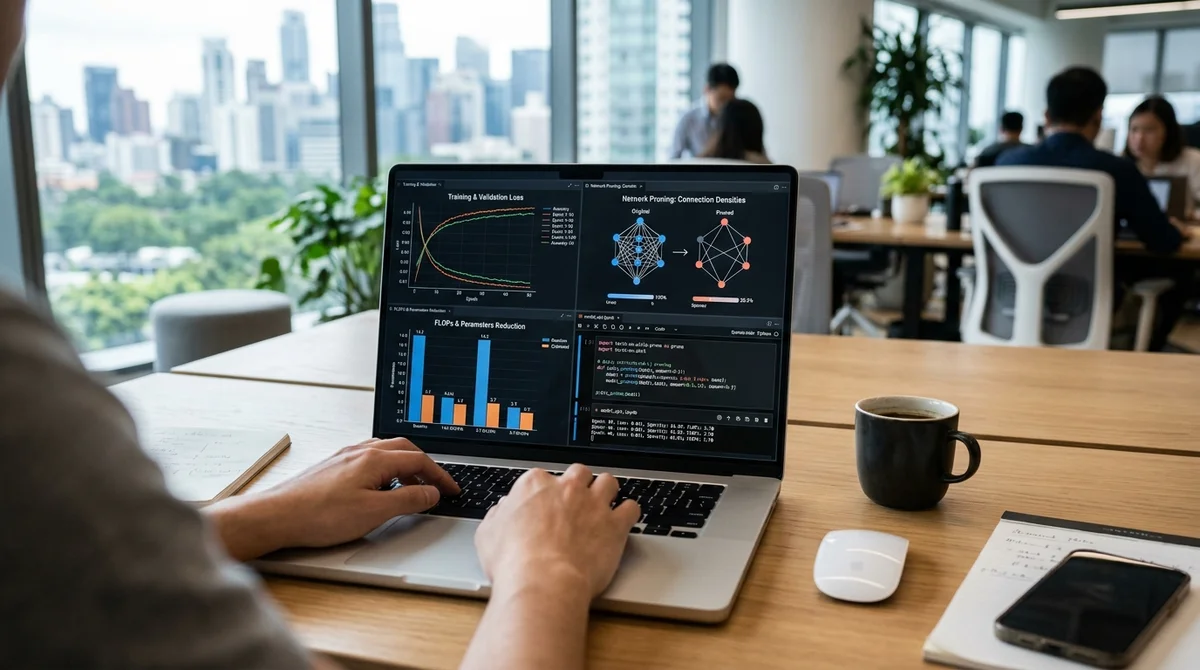
NVIDIA has published a hands-on guide that walks through a full neural-network optimization cycle in a single Google Colab notebook: from baseline training to structural pruning and subsequent fine-tuning. As its example, the company uses its NVIDIA Model Optimizer library, the CIFAR-10 dataset and a ResNet20 model, showing in real code how to cut a network's computational load without turning the process into a pile of disconnected scripts and manual experiments.
The guide starts by setting up the environment and preparing a reproducible experiment. It installs nvidia-modelopt, torchvision, torchprofile and supporting dependencies, fixes the random seed and run parameters, and then assembles a simplified but working configuration for Colab. Batch size is set to 256, the baseline model trains for 20 epochs, and the post-pruning fine-tuning stage takes another 12 epochs.
To speed things up, it uses subsets of CIFAR-10: 12 thousand images for training, 2 thousand for validation and 4 thousand for testing. The authors then define ResNet20 by hand in PyTorch, with residual blocks, custom weight initialization and explicit shortcut-connection logic. It is not a black box but an architecture that can be quickly adapted to your own task.
The guide puts particular emphasis on the engineering scaffolding. Training uses standard augmentations, including a random 32x32 crop and horizontal flip, while evaluation applies only normalization. Training itself uses SGD with momentum 0.9, weight decay 1e-4 and a cosine-decay learning-rate scheduler with warmup. The code has separate functions for a single training epoch, validation, testing, and saving the best checkpoint by validation accuracy. This detail matters: NVIDIA demonstrates not only the compression technique itself but a complete, reproducible pipeline in which you can track model quality before and after optimization, rather than simply running pruning as a one-off trick.
The key stage is FastNAS pruning. The example sets a limit of 60 million FLOPs, and the search configuration is set so that the number of channels and features stays a multiple of 16. The score function is validation accuracy, and before the run the authors separately patch compatibility with torchprofile so that FLOPs are counted correctly in Colab. Model Optimizer then builds a lighter subnet, saves it, and lets you restore the already optimized architecture for the next step.
This shows how NVIDIA positions Model Optimizer: not just as a pruning library but as a single layer for model-optimization techniques. In the official repository, the company describes it as a toolkit for pruning, quantization, distillation, sparsity and other methods, which can then be plugged into inference infrastructure such as TensorRT, TensorRT-LLM or vLLM.
Once the optimized subnet is found, fine-tuning begins. The restored pruned model is first re-evaluated, then retrained with a gentler learning rate, and finally the guide compares accuracy before pruning, after pruning and after fine-tuning. It also computes the total parameter count, the number of nonzero weights, and the time spent on each stage: baseline training, the FastNAS search and quality recovery. All key artifacts are saved too: the baseline state dict, the search checkpoint, the pruned model and the final optimized version.
For practicing ML engineers, the value is that the workflow can be repeated on their own architecture almost unchanged and built into the process of preparing a model for cheaper, faster inference.
The main takeaway is that NVIDIA treats model optimization as part of the standard ML pipeline rather than a separate task at the final stage before deployment. That approach matters particularly now, when compute costs, latency constraints and deployment requirements increasingly shape architectural decisions as much as accuracy itself does.
The material's strength is its applied logic: it shows how to move from a dense baseline network to a more efficient version through a reproducible, clear process that can realistically be run even in Google Colab.
- Nov 1, 202616 models tested on 7 search tools: Exa averaged 10.5 out of 14, SearXNG about 3
- Nov 1, 2026Google's StreamVibe video agent beats other models by 10.7% on response timing and quality
- Nov 1, 2026OpenAI Rewrites GPT Behavior Rules: Five Values and a Chain of Command
- Nov 1, 2026Voice bots built on LLMs turn to Jev, a fast classifier, for decisions in 200–500 ms
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.