Nvidia shows neural texture compression for games, cutting VRAM use nearly sevenfold
At GTC 2026, Nvidia showed one of the most practical AI technologies for games yet: Neural Texture Compression. In the demo, video memory use dropped from 6.5 GB to 970 MB at comparable quality. The idea is that textures are stored more compactly and reconstructed in shaders by a small neural network, which could ease pressure on VRAM in future releases.
AI-processed from 3DNews AI; edited by Hamidun News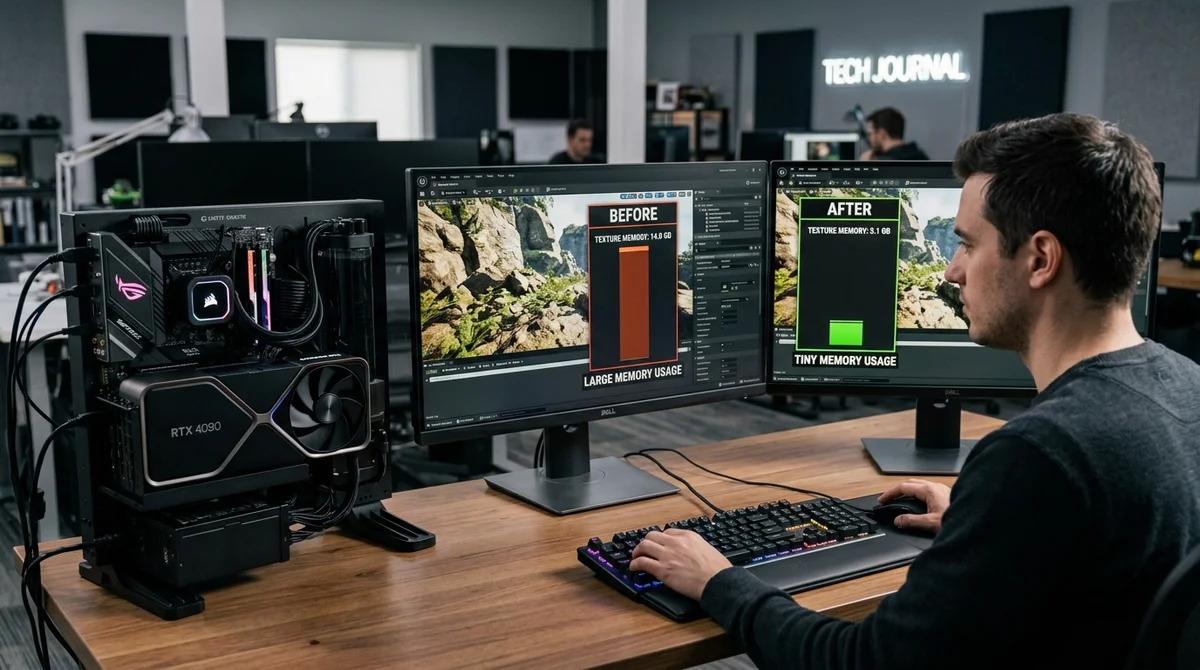
Nvidia showed at GTC 2026 that the video memory shortage in games can be tackled not only with pricier GPUs, but also by changing how textures themselves are handled. At the conference in San Jose, held on March 16–19, 2026, the company demonstrated Neural Texture Compression, a system that cut VRAM use in a test scene from 6.5 GB to 970 MB at comparable visual quality. For an industry where texture size has long been one of the main constraints, this looks less like a lab trick and more like a very practical step.
In essence, this is neural compression of materials. Instead of storing large sets of textures in familiar block-based formats, Nvidia proposes encoding them into a compact representation and then reconstructing them on the fly during rendering with a small neural network. The network is trained for a specific material and runs directly in shaders, using the tensor cores of RTX graphics cards. Importantly, the technology does not require abandoning existing graphics pipelines: developers can plug it in as a separate tool in a build and scene-output process they already know.
The idea itself is not new for Nvidia. The company published research on the topic back at SIGGRAPH 2023, and is now showing how the approach is moving from a research project to an applied SDK for game engines and graphics applications. In its official materials, Nvidia says neural compression can save up to seven times more VRAM or system memory than traditional formats at the same quality level.
In earlier examples, the company also showed that the approach preserves higher effective detail: in one comparison, neural-compressed textures delivered four times the resolution in less memory than high-quality block compression. Down the line, this could also affect the size of game packages, since the benefit extends beyond graphics card memory to data storage.
Why this matters right now needs little explanation. Modern games are increasingly limited not only by compute power but by memory: open worlds, 4K and 8K textures, complex materials, path tracing and large numbers of unique assets quickly eat up VRAM even on powerful graphics cards. When memory runs short, the result is aggressive data streaming, microstutters and unpleasant compromises in quality. If textures can be stored several times more compactly and still decoded on demand, developers get more freedom in filling a scene, and players have a better chance of hitting the hard memory limit less often.
The technology does have limitations, of course. It is not a magic switch that automatically makes any old game leaner. It requires developer-side tooling, training of small models for specific materials, and support for a modern GPU stack, including acceleration of such computations through Tensor Cores and new mechanisms like Cooperative Vectors in DirectX. In other words, a broad effect will appear only when NTC support starts being built into real game projects, not just tech demos and the SDK.
But the main conclusion is already fairly clear: Nvidia has found one of the few AI uses in graphics where the benefit is measured not in marketing promises but in very concrete megabytes. Neural Texture Compression does not try to "paint in" a scene on behalf of the artist; it tackles a narrow, expensive problem: how to fit more visual complexity into the same amount of memory. If the technology really reaches mainstream games without a noticeable loss in quality or performance, the debate over how much VRAM new releases need could become noticeably less painful.
- Nov 2, 2026Anthropic needs to grow revenue 32% a year to cover $850 billion in contracts
- Nov 2, 2026TensorFold 1.2.0 boosts Qwen3.8-27B throughput on M3 Ultra by 44.2% at 16 streams
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Habr author fine-tunes YOLOv8l on dental X-rays and pushes mAP50 to 0.642
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.