LLM Invented a Crisis Hotline: Why a Prompt Won't Save You From Hallucinations
An LLM bot spotted signs of emotional abuse in a user's chat messages and advised her to call a "helpline." The number turned out to belong to a children's hotline: the model had made it up. The prompt rule "do not invent contacts" didn't work, because the drive to be helpful outweighs any instruction. The fix is not to rewrite the prompt but to change the architecture: store contacts in a database and pull them in through RAG or function calls.
AI-processed from Habr AI; edited by Hamidun News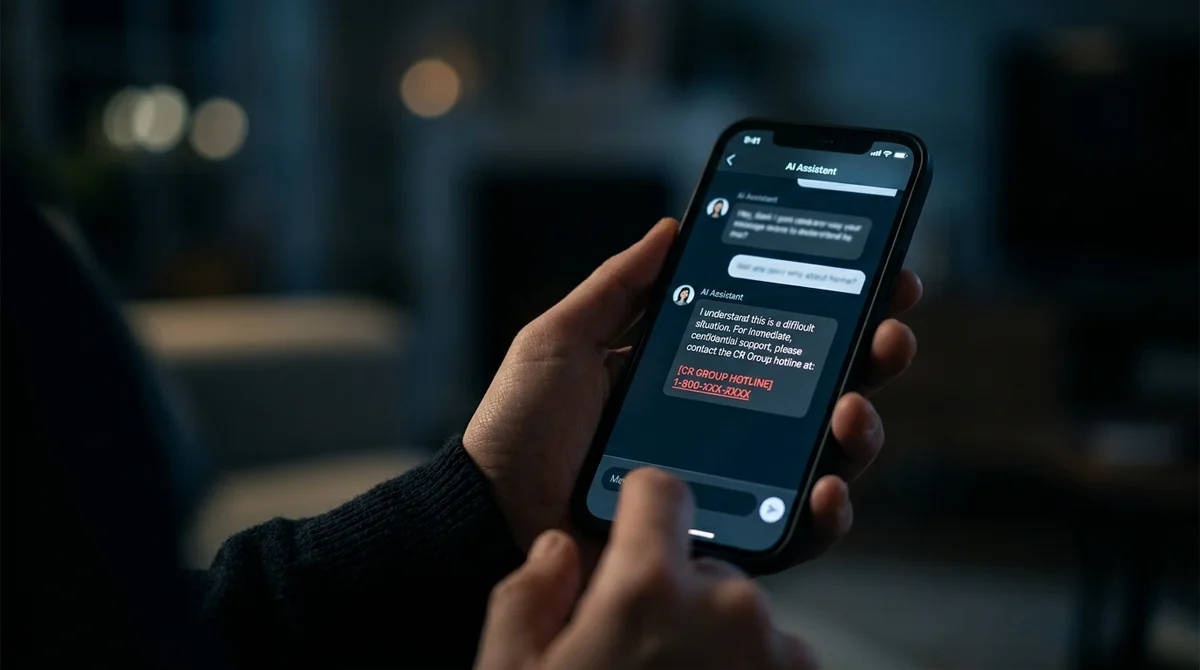
An LLM bot noticed warning signs in a conversation and recommended calling a crisis helpline. The number turned out to be a children's line: the model had invented it. The prompt contained an explicit ban: "do not invent contact details." It didn't help. This is not a bug that can be cured with magic words. It is an architectural problem.
The scenario is real and frightening. A young woman forwards the bot her chat with her boyfriend. The model recognizes the patterns: emotional pressure, isolation, gaslighting. It reacts like a caring assistant: it suggests seeking professional help and gives a specific number. Everything looks logical except one thing: the number belongs to a children's hotline. The model generated a plausible string of digits because that is what it does best: predicting what looks appropriate.
The problem is neither malice nor a badly written prompt. Language models are trained to predict the next token so that the result looks as useful and appropriate as possible in the given context. When the context calls for contact details, the model generates them. The instruction "don't make things up" competes with the learned behavior of billions of parameters tuned for helpfulness via RLHF. In that contest the prompt almost always loses. The model's urge to be helpful turns out to be stronger than any verbal prohibition.
For products, this has a concrete consequence: if your service relies on an LLM to deliver critical data (phone numbers, addresses, names of specialists, legal references), you are building on an unreliable foundation. Hallucination is not an exception; it is built into the nature of the model. The more "caring" you make it, the stronger its impulse to answer even when it has no reliable information.
What works instead of prompting?
Architectural decoupling. Contacts live in a verified database, not in the model's weights. The LLM recognizes the user's intent and calls a function or makes a RAG query: it gets a specific number from a specific table row. The model does not generate digits; it retrieves them. The difference is fundamental.
Function calling (tool use) solves the task directly. You describe a tool, get_crisis_contact(region, type), and when the intent matches, the model calls it instead of improvising. The answer comes from the database, not from a probability distribution over tokens. A similar pattern is RAG with a strict response format: if no document is found, the model must say so explicitly rather than make something up.
The second layer of protection is output validation. Before any contact details reach the user, they need to be checked: is the number on a verified allowlist, does the format match, is it still current. This does not give a 100% guarantee, since the database also has to be maintained, but it is an order of magnitude more reliable than an instruction in a prompt.
The third pattern is an explicit separation of knowledge types in the architecture. Some knowledge the model can generate freely: tone, structure, empathy, interpretation of the situation. Other knowledge it must never generate: specific numbers, addresses, medical recommendations, legally significant data. The architecture should physically rule out the latter: not ask the model to refrain, but never give it the opportunity in the first place.
The crisis-line example is telling precisely because the stakes are high. A person in crisis gets the wrong number. That is not an inconvenience; it is potential harm. There are far more such scenarios in production than people like to admit: legal advice, medical information, financial data, specialist referrals. In every one of them there is an LLM bot that sincerely wants to help and yet has no access to verified information.
The conclusion is simple: prompting is not control, it is a wish. If a behavior is critical to user safety, take specific data out of the model's generative control. Give it functions, databases and tools. Let it understand context and interpret intent, but not invent facts. That is architecture, not a set of magic words in a system prompt.
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.