MarkTechPost breaks down the full LLM training cycle, from data to deployment
A modern LLM is not one big training run but a long pipeline: pretraining, SFT, LoRA/QLoRA, RLHF, reasoning optimization and deployment. MarkTechPost's breakdown shows that a model's core capabilities emerge while it works through raw data, while its practical usefulness comes later, when it is fine-tuned for a task, aligned with human expectations and prepared to run under load. The article's main takeaway is that LLM quality comes from a chain of decisions across the whole route, not from a single secret stage.
AI-processed from MarkTechPost; edited by Hamidun News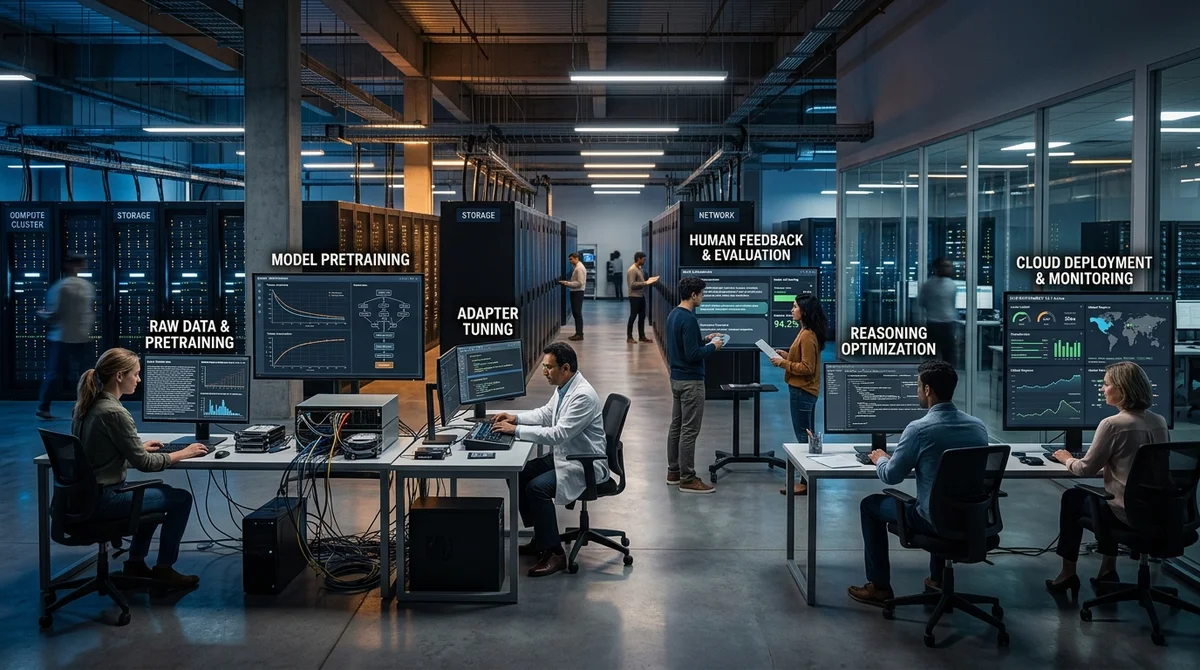
A large language model is not born in a single pass over data. It is a long engineering chain in which a mistake at any stage hits quality, safety and operating cost. MarkTechPost's technical breakdown describes the full route of a modern LLM, from pretraining to production deployment, and shows why two models of similar size can behave completely differently. The difference comes not from architecture alone but from the quality of the whole pipeline: data, behavior tuning, alignment and infrastructure.
The first stage is pretraining. Here the model receives huge volumes of raw data: books, websites, documentation, code and other text corpora. It is not taught a specific business task. Instead, it picks up general patterns of language, links between concepts, the structure of argumentation and basic reasoning patterns. Typical objectives are next-token prediction or filling in gaps. In essence, pretraining turns a randomly initialized neural network into a system that can continue text meaningfully and hold context. If this foundation is weak, no later improvement will produce a truly strong result.
Next comes supervised fine-tuning, or SFT. The model is no longer fed a plain mass of text; it is trained on labeled input-output pairs. This lets developers adapt it to specific instructions, answer style, tone of communication and industry rules. A simple example shows the difference: a base model may answer a user complaint tersely and dryly, while after SFT it can give a structured, polite and useful answer with clear steps. This is the stage where domain expertise, company requirements and the desired communication format are built into the model. In other words, pretraining answers the question of what the model can do at all, while SFT answers how exactly it should behave in a given applied scenario.
But full fine-tuning of large models is too expensive, so efficient adaptation methods are widely used in practice. MarkTechPost singles out LoRA and QLoRA. With LoRA, the base model weights are frozen and training happens only through small low-rank matrices inserted into selected layers.
This sharply reduces the number of trainable parameters, memory load and training time. QLoRA goes further: it combines the same approach with quantization of the base model, for example to 4 bits, so even very large models can be adapted without excessive infrastructure requirements. The practical point is simple: a company no longer has to run a full retrain for every new task.
It can take a strong base and tune it relatively cheaply for lawyers, support, analysts or an internal assistant.
Then alignment comes into play. Even if a model knows a lot and follows instructions reasonably well, it can still respond too harshly, unsafely or simply not as the user expects. This is where RLHF, reinforcement learning from human feedback, is used. People compare several model answers and rank them, a reward model is trained on that basis, and the LLM itself is then optimized to produce the preferred variants more often.
The article also mentions GRPO, a more recent approach aimed at improving reasoning and multi-step solutions. The model generates several candidate answers to one query, and training then relies not on an absolute score for each answer but on comparison within the group. This mechanism is especially useful where the quality of the reasoning matters as much as the final reply: math, logic problems, step-by-step explanations.
The final stage is deployment, and this is where a research model becomes a product. In production, what matters is no longer loss or dataset quality in themselves but latency, inference cost, throughput, GPU utilization and stability under real load. So models are optimized further: quantized, run through specialized inference engines such as vLLM, TensorRT-LLM or SGLang, wrapped in an API and hosted either in the cloud or in a self-hosted environment when data control and economics matter. On top of this comes observability: monitoring of latency, throughput and memory consumption, plus automatic scaling. Without it, even a strong model quickly turns into an expensive and unstable service.
The main conclusion of MarkTechPost's breakdown is that LLM quality is determined not by one "secret" stage but by the combination of decisions along the whole route. Pretraining supplies the raw intelligence, SFT makes the model useful for a specific task, LoRA and QLoRA make adaptation cheaper, RLHF and GRPO polish behavior and reasoning, and deployment decides whether the whole system can work live, fast and predictably. For the market, this is an important signal: competition between AI products is shifting more and more from model size as such to the quality of the engineering setup around it.
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026MoneyGate safety layer blocked all 42 fraudulent requests to local AI models
- Nov 1, 2026ThinkJev Makes AI Think Only About Hard Questions: 28% Fewer Tokens
- Oct 31, 2026Open-source LLM gateway KTMS 1.0 plugs your own GPUs into the cloud and survives outages
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.