WisprFlow, Whisper and GigaAM: Which Handles Mixed Russian-English Speech Best
Voice input for prompting AI models and working with code hinges not on speed but on handling mixed Russian-English speech. A new review compares WisprFlow, OpenWhispr, Handy and several models, including Whisper, GigaAM v3 and Canary 1B v2. The main conclusion: local open source tools can already replace cloud services without a noticeable drop in quality, and a well-chosen text prompt almost completely fixes punctuation.
AI-processed from Habr AI; edited by Hamidun News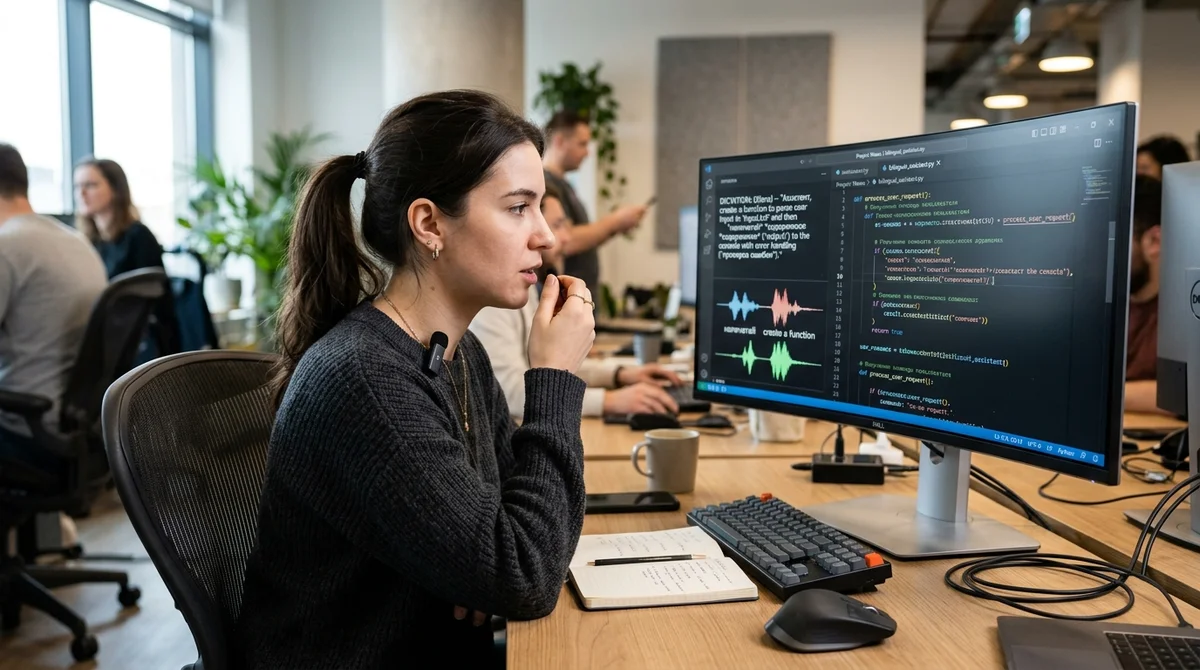
Voice input is no longer just a convenient add-on. For people who talk to LLMs, work in Cursor and dictate commands that mix Russian and English, it is becoming a full interface. In a new write-up, the author compared apps and models that need to understand phrases like "объясни на русском" ("explain in Russian"), "открой в Cursor" ("open in Cursor") and "проверь, что deploy прошёл" ("check that the deploy went through"), and showed which solutions are actually usable for this kind of mixed speech in 2026.
The review draws on six months of hands-on testing. It focuses not on abstract per-language recognition accuracy but on a harder scenario familiar to developers, analysts and heavy AI users: switching quickly between Russian and English within a single sentence, rendering product names, terms and code elements correctly, and producing clear punctuation without lengthy post-processing. This is where even strong systems often break: English words turn into Cyrillic, commands lose their meaning, and dictated text needs manual fixes.
On the app side, the author compared five options from different categories: WisprFlow, SpeakFlow, Handy, OpenWhispr and SuperWhisper. The sample includes cloud and local tools, paid products and open source projects. One of the review's key findings is that cloud-based WisprFlow can already be replaced by a free open source alternative without a noticeable loss in quality. For users, that means not just savings on a subscription but also more control over privacy, speed and the settings of a local pipeline. The author also notes a contribution to the ecosystem: one of their pull requests was merged into the main branch of an open source project.
The model section is just as important. The benchmark included Whisper Large v3, Whisper Turbo, GigaAM v3 from Sber, Canary 1B v2 from NVIDIA and Parakeet V3. Whisper remains the baseline in such comparisons, but the article shows that real-world results depend not only on the model itself but on how it is run. The author compared Whisper Turbo and Large v3 on an RTX 5070 Ti and got an unexpected result: on the Blackwell architecture, running through Vulkan was roughly 50% faster than through CUDA. For local setups this is a practical detail that matters, because the difference directly affects latency, how smooth dictation feels and the overall choice of stack.
Whisper alternatives no longer look like pure experiments either. According to the author, GigaAM v3 and Canary 1B v2 do get close to the leader in a number of scenarios, but their weak spots show up in mixed speech, when an English word must be neither translated nor transliterated but preserved intact. One telling example from the review is Gemini turning into "Jemni" (rendered in Cyrillic by the model). In an ordinary note that is annoying but tolerable; when you are voice-controlling AI tools, IDEs, library names and deployment commands, such an error can break the meaning entirely. That is why, in technical use, code-switching quality matters more than an averaged accuracy metric.
Another practical finding concerns punctuation. The author writes that the problem of missing commas and periods was solved in 99% of cases with a single text prompt, with no LLM post-processors and no added latency. This matters for anyone building a voice workflow around editors, AI chats and notes: the friction often comes not from misrecognized words but from having to clean up the text afterward with separate processing layers. If punctuation can be stabilized at the baseline level, voice starts to compete with the keyboard not only on speed but also on everyday convenience.
The review's conclusion is simple: by April 2026, the market for voice input in mixed Russian-English has matured noticeably, but there is still no universal winner. If you need the most predictable result, Whisper and the strong apps built around it still set the bar. If locality, price and control over the stack matter, open source solutions already look like a real alternative to cloud services. And the main criterion becomes not advertised "accuracy" but the ability of a system to get through live technical speech without failures, where Russian, English and commands for neural networks all appear in one sentence.
- Nov 1, 202616 models tested on 7 search tools: Exa averaged 10.5 out of 14, SearXNG about 3
- Nov 1, 2026Google's StreamVibe video agent beats other models by 10.7% on response timing and quality
- Nov 1, 2026OpenAI Rewrites GPT Behavior Rules: Five Values and a Chain of Command
- Nov 1, 2026Voice bots built on LLMs turn to Jev, a fast classifier, for decisions in 200–500 ms
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.