Anthropic's Claude Opus 4.7 Burns More Tokens Than Advertised
Claude Opus 4.7 ships with a far hungrier tokenizer than Anthropic promised. In two practical measurements, token counts rose 1.47x on technical documentation and 1.45x on a real CLAUDE.md file, against the stated 1.0–1.35x. For users, that means quotas drain faster, the cached prefix costs more, and rate limits arrive sooner, even though prices and plan terms have not changed.
AI-processed from Habr AI; edited by Hamidun News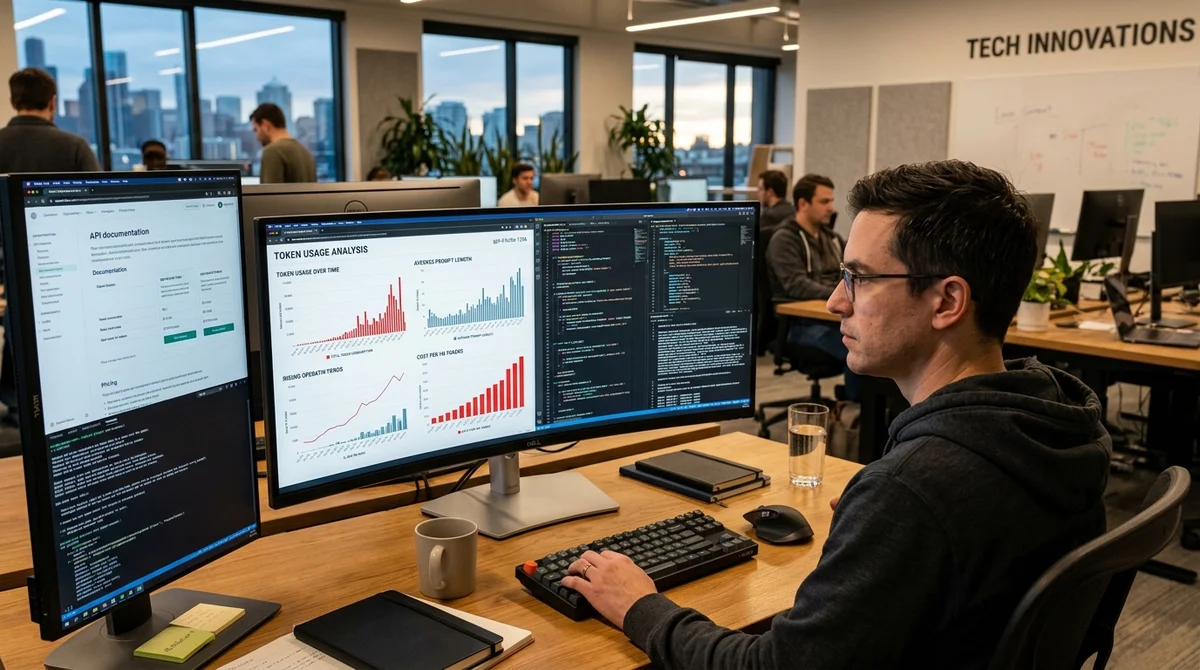
Claude Opus 4.7's new tokenizer can make the model noticeably more expensive to use: in real tests, token consumption rose by roughly 45–47%, not the 0–35% that Anthropic cites in its migration guide. For teams working with long prompts, large system instructions and cached prefixes, this is not a cosmetic difference. It hits quotas, speed and the cost of every session directly.
The gap between promise and practice prompted the analysis. Anthropic's documentation says the new tokenizer uses roughly 1.0–1.35 times as many tokens as the one in Opus 4.6. The author chose to test this not on abstract examples but on material that resembles real developer workloads.
In the first measurement, he ran technical documentation through the tokenizer and saw an increase of up to 1.47x. In the second, he took a real CLAUDE.md file, a large block of instructional context, and got almost the same result: 1.45x. The distance from the upper bound in the guide is too large to dismiss as ordinary measurement noise.
The problem is not the increase in tokens itself. Sometimes a heavier tokenizer does deliver gains in quality, stability or handling of complex text. The issue is that Anthropic has changed neither prices nor quotas. If the same text now takes more tokens, users hit context limits sooner, run into rate limits earlier and spend more budget on every iteration.
This is especially painful for setups with a long system prompt, a set of rules, example answers, chunks of documentation and a cached prefix that is sent again and again. On paper the plan is the same, but its usable capacity is actually smaller.
That is why the author went beyond simple counting and tried to work out what the model gives in return. According to the description of the experiment, he checked the claimed benefits of the new tokenizer and its behavior on practical tasks. The key finding is that no miraculous compensation appeared: at least in the tested scenarios, the rise in consumption was very noticeable, while the payoff did not look equally obvious or systematic.
In other words, from the point of view of someone who pays for tokens or lives within subscription quotas, the trade does not favor the user. That does not necessarily mean Opus 4.7 is a worse model, but it does mean its economics have become less comfortable.
This is an important signal for the market. Tokenizers are rarely discussed outside a narrow circle of engineers, yet they determine how much real text fits in the context window and what each API operation costs. A 5–10% difference is often tolerable and can get lost in the normal variability of requests. But a jump of about 45% is no longer a technical detail. It affects agent architecture, the length of system instructions, caching strategy and even a product's unit economics. If a team has a pipeline where the same large prefix appears in hundreds of calls, the extra tokens start eating money and throughput very quickly.
The practical takeaway is simple: evaluate a move to Claude Opus 4.7 against your own text corpora, not the marketing wording in the migration guide. Run system prompts, instruction files, documentation, agent task templates and anything else that often lands in context. If measurements show an increase close to 1.45x, the team may have to trim prompts, move some logic out of the context, rethink caching or even postpone migration until the benefit is clearer.
The main lesson is that a model's quality cannot be judged by demos and benchmarks alone: sometimes what decides the outcome is not the intelligence of the answer, but the price of each extra token.
- Nov 2, 2026Karpathy builds a YouTube clone with 6454 videos from Hacker News recommendations in two hours
- Nov 2, 2026Karpathy used Claude to build HackerTube from 6,454 videos recommended on Hacker News
- Nov 2, 2026Arca gives AI agents finance tasks lasting up to 10 days, but leaves the trades to humans
- Nov 2, 2026Anthropic needs to grow revenue 32% a year to cover $850 billion in contracts
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.