Why LoRA Breaks in Production and How RS-LoRA Rescues Model Fine-Tuning
LoRA works well when a model only needs a new tone, format or persona, but it struggles when you need to add new facts. A low rank cuts off a high-dimensional signal, and simply raising the rank weakens the training signal. RS-LoRA proposes a simple fix: use alpha/√r instead of alpha/r, which keeps training stable at higher ranks.
AI-processed from MarkTechPost; edited by Hamidun News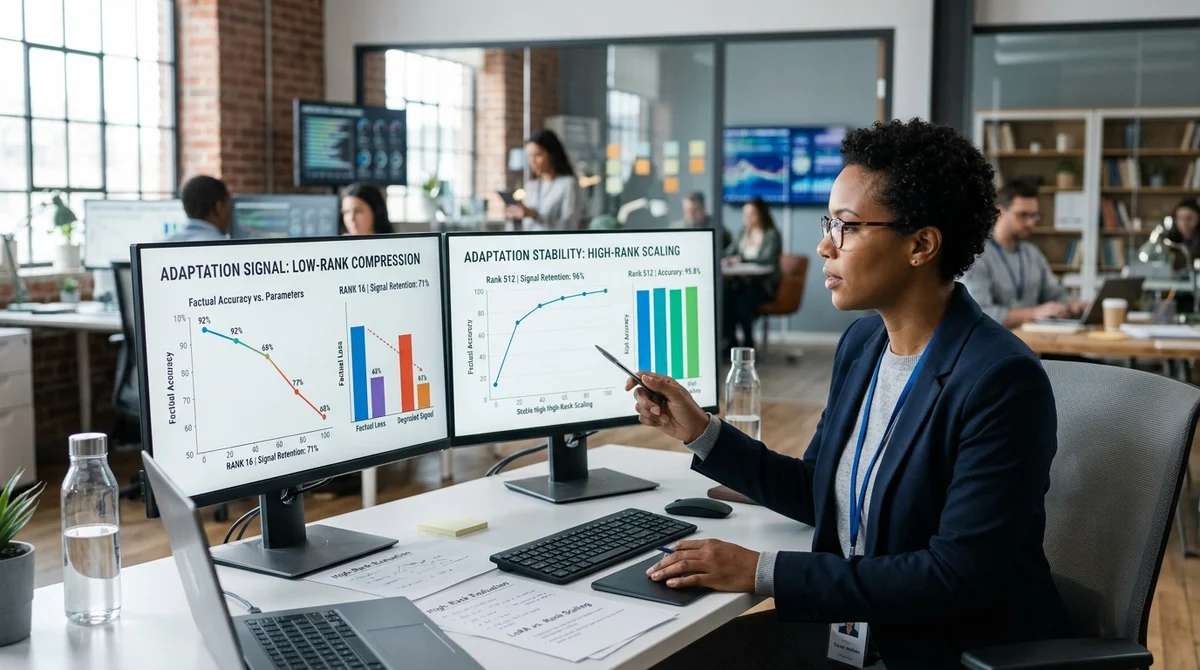
LoRA has long been the standard for cheap fine-tuning of large models, but in production it carries a hidden assumption: that all weight updates look alike. In practice they don't. Changes that govern style really are compact, while updates that add new facts and domain expertise are spread across many dimensions, and that is where ordinary LoRA starts losing information.
LoRA's popularity is easy to explain: the method fine-tunes a model without recomputing all of its parameters, using small low-rank matrices. This works well when you need to change an assistant's tone, response format, character or speech habits. The paper demonstrates this on a simplified 64×64 weight matrix: in a style update, a few singular values dominate sharply, so a rank-4 or rank-8 approximation preserves almost all of the signal. In their simulation, rank 4 already captures more than 99% of the useful variation. That is why a chatbot easily learns a new communication style, response template or desired manner without heavy retraining of the whole model.
Problems begin when the goal is to teach content rather than form: medical facts, product catalogs, internal policies, statistics or industry rules. Such updates behave as high-rank: the information is smeared across many directions instead of concentrated in a few dominant components. In the paper's experiment, rank 8 retains only about 28% of the actual signal.
Hence a familiar production effect: the model sounds confident, uses the right terminology and the general structure of an answer, but mixes up figures, misses details or gives an incomplete conclusion. For enterprise assistants, analytics, support and knowledge-driven scenarios, this is no cosmetic flaw but a quality risk.
The key difference shows up in the singular value spectrum. Style tasks have a clear elbow: after a few components, additional dimensions add almost nothing. Facts have a long tail, where each further component contributes part of the useful knowledge. When LoRA hard-truncates such an update to a low rank, it cuts off exactly that tail. The system can still look improved from the outside, because format, tone and structure became tidier, but factual accuracy improves much less than superficial tests suggest. This explains why demos with polished answers and good style do not guarantee reliable behavior on real working data.
The logical reaction for an engineer is to simply raise the rank. But standard LoRA has a second hidden problem: the alpha/r scaling. The higher the rank, the more the coefficient shrinks and the weaker the training signal becomes.
In the example with alpha = 16, the scale falls from 16 at rank 1 to 0.25 at rank 64. The result is a paradox: you add capacity so the model can represent a more complex update, but at the same time you reduce that update's real influence on the weights.
The optimizer has to compensate with more aggressive steps, so training either converges worse or becomes unstable. That is why the advice to raise the rank often does not solve the problem in production, and sometimes only masks it.
RS-LoRA offers a minimal but important fix: use alpha/√r instead of alpha/r. Formally it is nearly a one-symbol change, but in practice the effect is large. At rank 64 the scale stays at 2.0 instead of 0.25, so high-rank adaptation keeps a meaningful magnitude and does not kill the signal.
The paper shows this without heavy training loops or frameworks, using only NumPy, SVD and a comparison of reconstruction errors. That makes the argument especially clear: low-rank style tasks are still handled well by ordinary LoRA, while knowledge-injection tasks require either RS-LoRA or a fundamentally different adaptation strategy.
The takeaway for teams shipping fine-tuned LLMs to production is fairly direct: choose the adapter configuration not only by budget and speed, but also by the type of update. If you are changing tone, persona or response format, standard low-rank LoRA is usually enough. If you are injecting new facts, reference data, rules or domain expertise, a low rank can create an illusion of successful training while quietly losing a substantial part of the information. In such cases RS-LoRA looks less like a fine optimization and more like a reliability requirement for the model in real-world operation.
Ship AI Faster with Founders, Engineers & Weekly Architecture Reviews
Inside Vibe Club (hamidun.com/club) — weekly live masterminds with Zhemal Khamidun, Tech Radar, full LMS access, and 370+ production Claude Code skills.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.