Habr AI explains how data-driven solution search reshapes client-server architecture
Expert systems with data-driven search need more than a knowledge base: they need a stable dialogue with the user at every step. A new analysis shows how a local install, a local-network deployment and internet access differ, what limits each model faces, and why architecture should be chosen by usage scenario, not by fashion. The approach only works if the system can keep guiding the user through a chain of clarifications. That makes architecture as important as the knowledge base itself. The key takeaway: in data-driven search, architecture is not a shell around the algorithm but part of the product itself.
AI-processed from Habr AI; edited by Hamidun News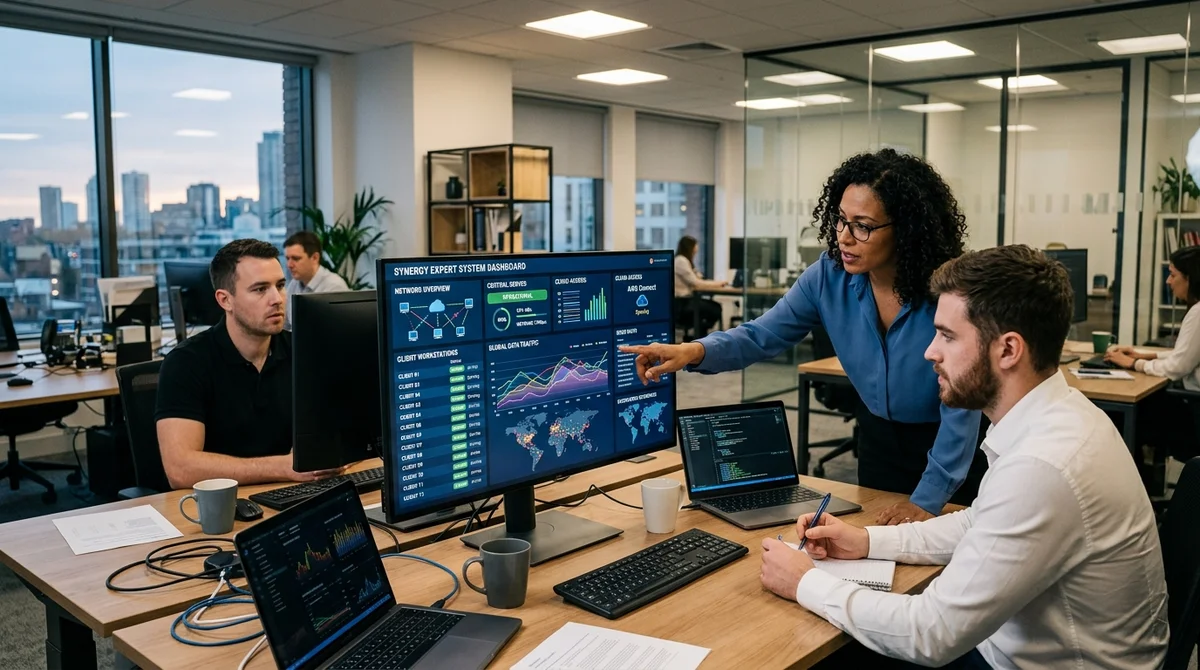
Data-driven solution search works only where the system can continuously guide the user through a chain of clarifications. That means architecture matters here as much as the knowledge base itself. The focus is not the interface as such, but how to organize a live dialogue between a person and an expert system when it has to serve several workstations at once without losing data consistency.
The point of the data-driven approach is that the system does not simply return a prepared answer to a single query. It matches input data, asks clarifying questions, checks constraints and gradually narrows the set of options. So the quality of the result depends not only on the rules inside the knowledge base, but also on how reliably user answers are transmitted, how fast the system responds, and whether it can continue the dialogue without losing context when several people or several devices take part in the process.
Habr AI's analysis centers on three basic interaction models: a local install on a single computer, operation within a local network, and access over the internet. At first glance the differences may look purely technical, but in practice they change the usage scenario itself.
If the expert system runs locally, it is simpler to deploy, does not depend on the network and suits isolated environments. This setup works well for pilots, narrow professional tasks and situations where autonomy and predictability matter. But its limits show up quickly: updates drift apart across workstations, work history fragments, and a single knowledge base turns into a set of copies.
A local network brings the next level of maturity. When several users connect to a shared knowledge base and a shared solution-search engine, the system starts to work as a corporate tool rather than a standalone program. Versions are easier to control, changes are easier to administer, and uniform decision rules are easier to enforce. New requirements appear as well: you have to think about concurrent work, access-rights separation, recording of user sessions, action logging and server resilience. Otherwise even sound recommendation logic quickly runs into organizational failures.
Web access over the internet makes the system more flexible still, because branch offices, remote specialists, partners and mobile users can connect to it. But this is where it becomes especially clear that the architecture discussion cannot be reduced to picking a trendy stack. What matters is not just pages, APIs or message transport, but where the dialogue state is stored, how a session is restored after a connection drop, how sensitive data is protected, and how quickly the user gets feedback at each step. For systems where finding a solution is a series of clarifications, delays, lost context or diverging versions can be more critical than for an ordinary reference tool.
It is also worth noting that the material deliberately stays out of implementation details. It does not discuss REST or SPA, long polling or WebSocket, server-side session or event sourcing. That is a strength of the approach: first define the interaction model between the user and the expert system, and only then choose specific development tools. Otherwise a team risks starting with technologies without answering a more important question: where exactly the decision-making logic should live, how the knowledge base will scale, and who is responsible for the integrity of the user experience when several clients work at the same time.
The main conclusion is simple: for data-driven search, architecture is not a shell on top of an algorithm but part of the product itself. The choice between local, network and web models determines speed of adoption, maintenance cost, version control, security and user convenience. The earlier this is factored into the design of an expert system, the lower the chance that a successful prototype will have to be rebuilt from scratch once it grows into a tool for a team, a department or an entire company.
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.