Scikit-LLM shows how to build text summarization into a scikit-learn ML pipeline
Scikit-LLM has shown how to build summarization directly into a familiar scikit-learn pipeline. In the example, long reviews are first compressed by the free DistilBART model from Hugging Face, then pass through TF-IDF and LogisticRegression. The approach shrinks the volume of text, simplifies feature preparation and keeps the whole process, from raw input to classification, inside a single reproducible pipeline.
AI-processed from Machine Learning Mastery; edited by Hamidun News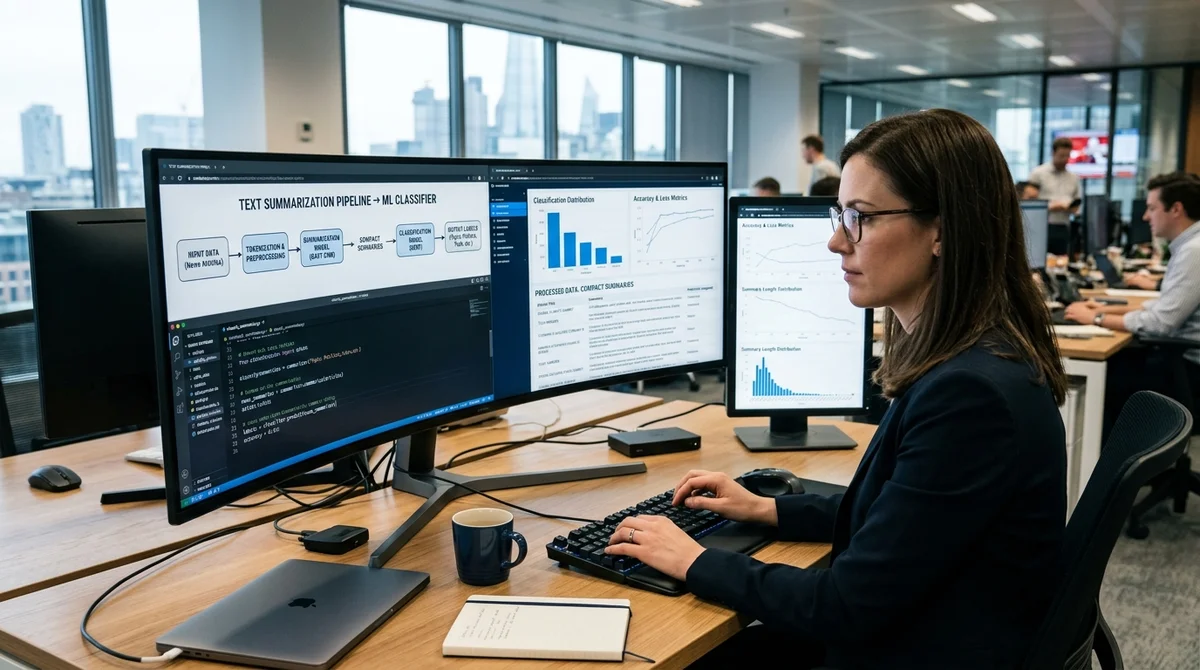
Scikit-LLM has demonstrated a practical way to build text summarization directly into a classic scikit-learn ML pipeline. The idea is simple: long documents are first compressed by an LLM into short summaries, then turned into numerical features and sent to a classifier. This lets you work with large texts without a separate manual preprocessing step and makes the whole pipeline a single unit, from raw text to the final prediction.
In the walkthrough, the author uses Scikit-LLM as the link between traditional machine learning tools and modern language models. By default the library relies on OpenAI models, but the example picks a free option through Hugging Face: the sshleifer/distilbart-cnn-12-6 model. This also requires installing the transformers library, version 4.37.2. The choice matters: summarization can be called many times, and inference costs quickly become noticeable if you run it on commercial APIs.
The key element of the example is a custom HuggingFaceSummarizer class compatible with scikit-learn. It inherits from BaseEstimator and TransformerMixin, so it can be dropped into a regular Pipeline like any other transformer. In the fit method, the class loads a pretrained model into memory; in transform, it takes a list of texts, runs the summarization pipeline and returns the finished short summaries. Hardware is also taken into account: if a GPU is available, the model runs on it, otherwise it uses the CPU.
This summarization then becomes the first step of the ML pipeline. It is followed by TfidfVectorizer, which turns the shortened texts into numerical features, and then LogisticRegression is trained on those representations. The demonstration uses just two examples: a positive review of a vacuum cleaner and a negative review of a backpack, citing delayed delivery and a faulty zipper. That is of course not enough for a real model, but the point is something else: showing that long unstructured text can be automatically condensed and fed straight into a standard classification setup.
It is also useful that the whole process is triggered by an ordinary fit call. At this step the pipeline downloads the model, summarizes the long texts, vectorizes the shortened versions and then trains the classifier. The author also shows the intermediate summaries themselves: the positive review keeps the idea that the device is good overall, although somewhat heavy and not immediately clear to set up; the negative one retains the complaints about delayed delivery, a sticking zipper and cheap fabric. Even a compact model can extract the main signal, which can then be used in ordinary ML.
As expected, the result of such a minimalist approach is a compromise. The author states plainly that the quality of the summaries is noticeably worse than what ChatGPT or Google Gemini can produce. The lightweight, free DistilBART model pulls out the main points, but does so more crudely and less carefully. Still, the example illustrates the architecture well: summarization becomes not an external tool but a built-in part of the training process. This is especially useful where there are many documents, they are long, and the downstream model is sensitive to dimensionality and text noise.
The practical value of this scheme is that a developer gets a single reproducible pipeline for preparing texts and training the model. Instead of several scattered scripts, there is one pipeline that can be trained, tested and moved to production under standard scikit-learn rules. If you swap the lightweight model for a stronger one, summarization quality will rise, and classification quality may rise with it. Scikit-LLM acts here as a bridge between the familiar machine learning stack and LLM approaches, one that can be adopted without rebuilding the infrastructure. It is especially interesting for teams already living in the scikit-learn ecosystem that want to add LLM features selectively, without rewriting entire pipelines, training infrastructure and validation procedures.
- Nov 2, 2026Meta's Muse assistant keeps dossiers on loved ones and gets root on Ubuntu by default
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Kimi scores 96.2% on a 1C database analytics test and emerges as a fallback if Claude access is blocked
- Nov 1, 2026OpenAI Rewrites GPT Behavior Rules: Five Values and a Chain of Command
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.