Databricks and Infosys: Why Data Is Slowing Enterprise AI Adoption
The main barrier to enterprise AI turns out to be duller than the models themselves: data. Companies want to move from chatbots to process automation and AI agents, but that requires unified storage, clear access rights, control over data lineage, and a link between analytical and transactional systems. Without that foundation, pilots look impressive, while scaling quickly runs into chaos and risk.
AI-processed from MIT Technology Review; edited by Hamidun News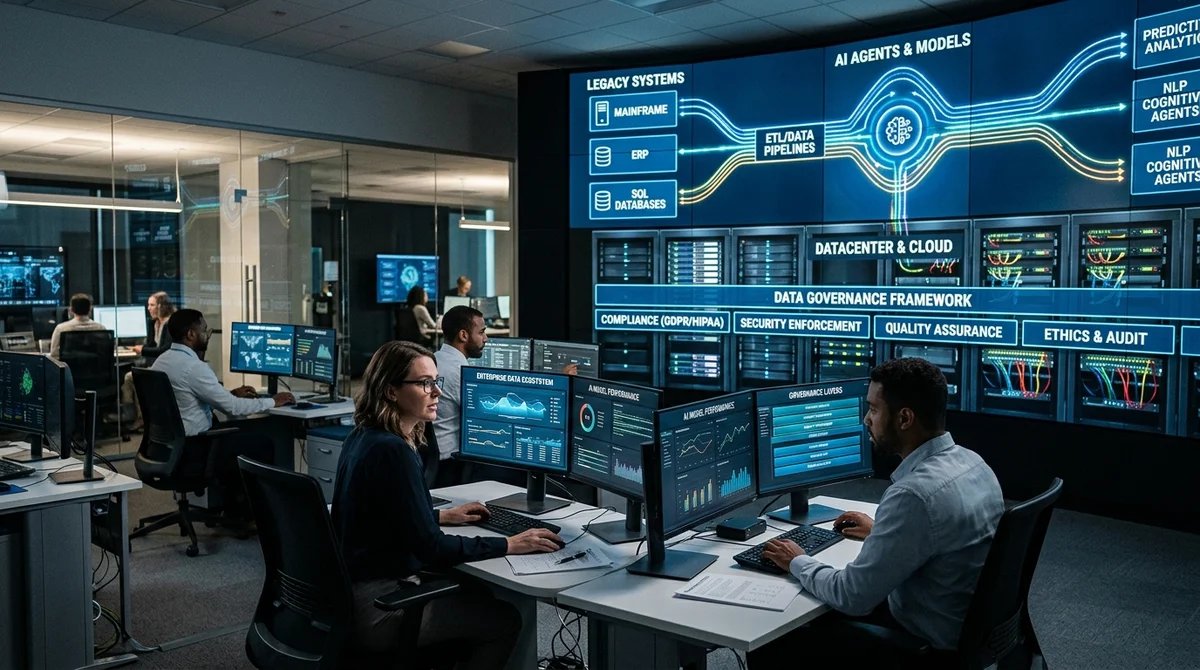
Companies are discussing artificial intelligence at the board level more and more, but real AI rollouts in business are slowed down more often not by models or compute, but by the state of corporate data. Consumer services have trained the market to expect instant results, yet inside large organizations a more prosaic reality quickly emerges: without a unified, governed and production-ready data infrastructure, AI remains a polished demo rather than a working tool.
The core problem is that corporate data usually lives in too many different layers. Some of it sits in analytical marts and data lakes, some in transactional systems such as CRM, ERP and internal applications, and some is scattered across files, email, knowledge bases, tickets and cloud services. For ordinary reporting, this landscape can still be tolerated.
But when a business wants to give a model access to real-time data, embed AI in processes or launch agents that not only answer questions but also take actions, fragmentation becomes a direct constraint. A model may be strong, but if it cannot see current context, does not understand where data comes from and does not operate within clear access rights, the result is unstable and risky.
That is why the conversation about enterprise AI is shifting from models to architecture. One of the key arguments is that enterprises need not a set of disjointed AI tools but a new data stack, where data is stored in open formats, described by metadata, available through unified policies and usable for both analytics and operational scenarios. Hence the interest in architectures that join the OLAP and OLTP worlds: on one side, companies need analytical depth, history and scale; on the other, low latency, transactionality and the ability to act quickly.
In this approach, Databricks promotes Lakebase as a serverless Postgres layer for operational AI workloads, and Unity Catalog as a unified layer for access control, data lineage and governance of data and AI assets. The point is not the specific products but the trend itself: business needs a foundation on which AI can run in production, not only in a pilot.
How to measure the impact is a separate question. At an early stage, companies are often satisfied with flashy metrics such as the number of chatbot queries or the percentage of employees who opened copilots. But as adoption matures, this is no longer enough.
If AI is supposed to automate processes, shorten operation cycles, raise conversion or create new revenue lines, it has to be assessed as a full-fledged business system. So the discussion of the new data stack also covers measuring value: AI's impact should be tied not to a wow effect but to concrete business results. This matters especially as the industry shifts to agentic AI, where the model gets more autonomy, and so the requirements for observability, logging, data quality and access policy become much stricter.
The evolution of enterprise AI looks fairly clear. First, companies adopt individual productivity tools: assistants for search, summarization, coding or document preparation. Then they move to process automation: handling requests, routing tasks, internal support, and financial and operational scenarios. Only after that does a third stage open up: launching new products and business lines built around AI from the start. At each stage, data requirements grow. What still worked for a personal copilot stops working for a process that needs accuracy, a full action log and the ability to perform operations safely on behalf of the company.
Hence the main conclusion: the next battle for enterprise AI is not over the best interface to a model, but over rebuilding data for machine use. The winners will not be the companies that plugged in the latest chatbot fastest, but those that managed to make their data unified, governed and compatible with agentic scenarios. For business, this means an unpleasant but useful truth: the path to AI at scale starts not with choosing a model, but with rebuilding the data stack.
- Nov 2, 2026Microsoft releases 4B model Mage-VL-Cowork, which solves 66.0% of OSWorld-Verified tasks
- Nov 2, 2026Meta's Muse assistant keeps dossiers on loved ones and gets root on Ubuntu by default
- Nov 2, 2026mcp-linter finds 18 undescribed parameters in Anthropic's filesystem server
- Nov 2, 2026The Verge reviewer builds a $50 Meta Muse Charm alternative with Claude Code
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.