The Testing Pyramid as a Task Decomposition Tool for AI Agents in QA Assist
QA Assist, a system of 11 AI agents, ran into a classic problem: because of its context window, a language model can't cover an entire project in a single request. The solution is the testing pyramid. Unit tests come first, then integration tests, then E2E. Each layer fits into the context and is generated in isolation. Mikhail Fedorov explains how to feed the elephant to a neural network one bite at a time, and why classic QA theory matters more than ever.
AI-processed from Habr AI; edited by Hamidun News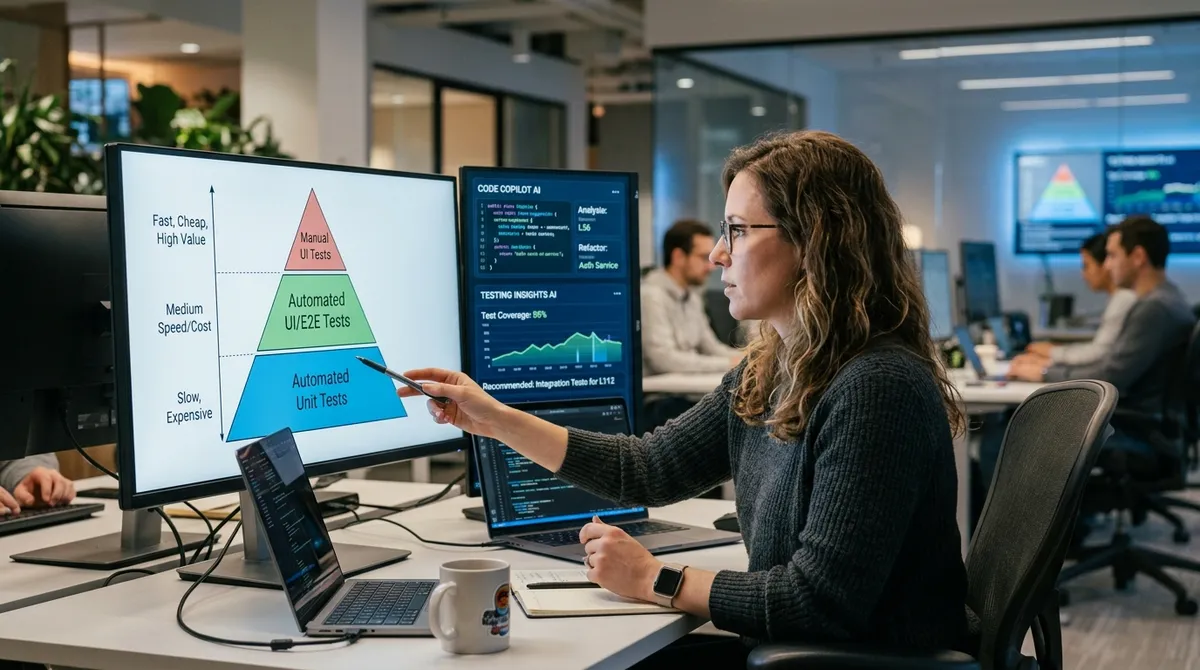
When a language model becomes the test designer, classic QA theory unexpectedly takes on a new dimension. That is the subject of the third article in Mikhail Fedorov's series on the QA Assist system, published on Habr. This time, the author explains why the testing pyramid, devised long before the era of neural networks, turns out to be critically important for AI agents with a limited context window.
QA Assist is a system of 11 specialized AI agents for automating software testing. In the first article of the series, Fedorov described the architecture: how responsibilities are split among the agents, how they interact, and what they can do. In the second, he gave an honest look at the reality of deployment: a task that looks like four hours of work on paper turns into a week of approvals, meetings with the security team, and edits to infrastructure configs in a corporate environment. The third article moves up a level, to the question of how to frame tasks for AI correctly to get high-quality, reproducible results.
The testing pyramid is one of the foundational principles of software development. At the base sit fast, cheap unit tests that check functions and methods in isolation. The middle layer holds integration tests, which check how components interact. At the top are slow, expensive end-to-end tests that simulate a real user scenario. The classic ratio: lots of unit tests, fewer integration tests, and a minimum of E2E. This structure saves time on test runs and simplifies debugging: when a unit test fails, it's immediately clear what broke.
The problem arises when a language model, rather than an engineer, designs the tests. An LLM works within a context window, a fixed number of tokens the model can hold in a single generation session. For small tasks, this isn't critical. But ask a neural network to write a full test suite for a large application in one request, and the outcome is predictable: either part of the business logic falls off the edge of the context, or the model produces shallow scenarios that never dig into the real dependencies and edge cases.
This is where the testing pyramid stops being textbook theory and becomes a practical decomposition tool. The author's metaphor, feeding the elephant to a neural network one bite at a time, captures the essence of the approach. The big task is split into layers following the pyramid: agents first generate function-level unit tests, then move on to integration scenarios, and only at the very end to E2E. Each layer fits into the model's context window and is processed in isolation, with no loss of quality from context overflow.
This approach delivers several concrete benefits. Every request to the model becomes focused: the agent gets a clear scope, a defined input contract, and a specific output artifact. Errors stay localized: if a unit test is written incorrectly, that shows up immediately, not several iterations later when an integration scenario has already been built on top of it. Finally, the pyramid sets a natural dependency order: E2E tests are built on top of a verified foundation, not in parallel with it.
Fedorov doesn't claim to have reinvented the wheel. The author himself acknowledges that this is a long-established engineering principle applied to a new context. But that is precisely the main point: AI doesn't abolish the fundamentals of software development; it makes them even more important. Understanding the testing pyramid is now necessary not only for QA engineers but also for anyone designing the architecture of requests to language models.
For teams considering AI tools for test automation, this is a practical lesson: design the task decomposition first, then hand it over to the model. You eat the elephant one bite at a time, and that's not a limitation of the technology but the only architecture that actually works.
- Nov 2, 2026Claude Opus 5 built simple baselines that closed 95.5% of the gap to DL models from Nature and Science
- Nov 2, 2026Manager-less DreamTeam swarm wrote trustcheck for $5.68 and passed 13 of 13 hidden tests
- Nov 2, 2026ASTC Compresses Agent Context Without Training, Cutting Attention Pairs by 50.68%
- Nov 2, 2026TraceSpec raises DSpark throughput for LLM agents by 12.5–22.6%
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.