OpenAI, Anthropic and Google dread one question from CTOs
AI tool vendors, from OpenAI, Anthropic and Google to dozens of startups, hope one question never gets asked: "What are the actual results?" Adoption of AI in software development is exploding, yet most engineering leaders still count active licenses rather than productivity or code quality. That is a costly blind spot, and this question is what separates effective technical leaders from the rest.
AI-processed from TNW; edited by Hamidun News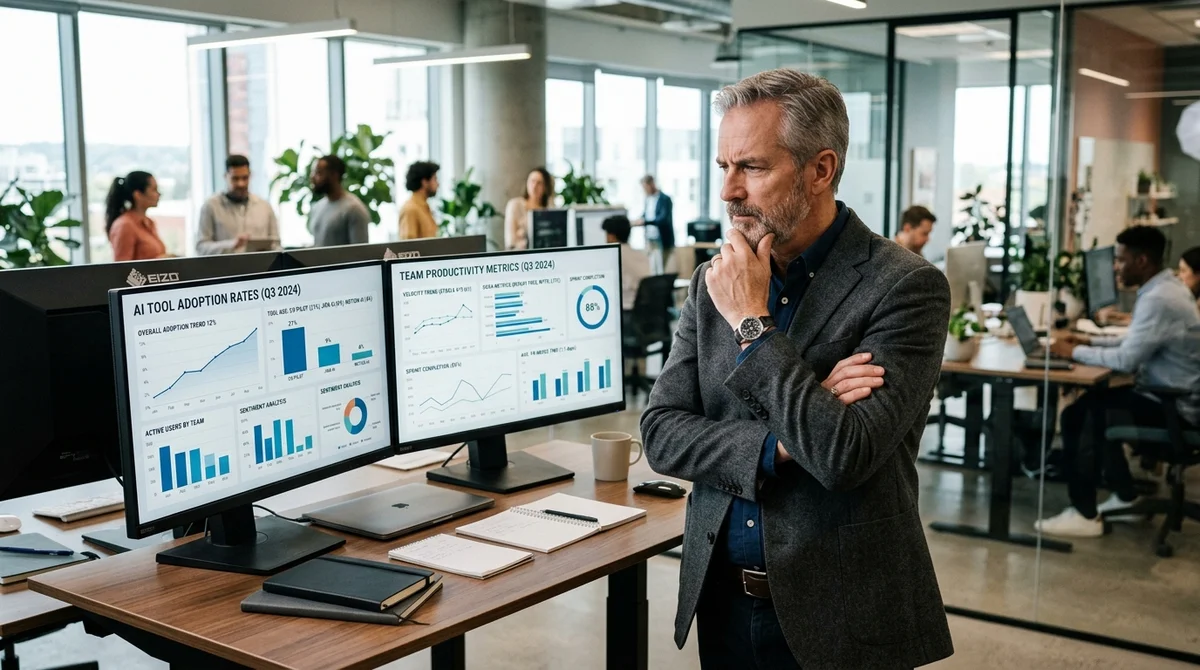
AI tool vendors for developers, from OpenAI and Anthropic to Google and dozens of startups building AI coding agents, share an interest in making sure engineering vice presidents never ask one particular question. Not "how many employees use the tool?" and not "how much has the volume of generated code grown?" What they really fear is the question: "what are the actual business results?"
Adoption of AI in software development is genuinely explosive. GitHub Copilot reports millions of active users. Cursor, Replit, Windsurf and dozens of lesser-known tools are capturing the budgets of tech teams worldwide. According to industry studies, more than 70% of developers at large companies already use at least one AI coding tool. Analysts estimate the entire market for AI developer assistants will exceed $10 billion by 2027.
But beneath these impressive numbers lies a serious problem. Most engineering leaders measure usage metrics, not outcomes. They know how many developers activated a license, how many lines of code the AI suggested and developers accepted, and what percentage of the team "actively uses" the product. But they do not track whether time to market for features has shrunk, whether production defects have declined, whether technical debt has decreased, or whether real development velocity has risen after adopting AI. It is a costly blind spot, and one that suits tool vendors perfectly.
The reason for the gap is clear: measuring usage is easy, while measuring real results is extremely hard. Assessing the true effect of AI on team productivity requires baseline data from before adoption, proper control groups, stable definitions of "productivity" (itself a subject of heated debate in the engineering community) and time: at least several quarters. Vendors care about license renewals and eye-catching marketing success stories, not rigorous studies that might show a modest or even negative effect in some scenarios.
The few independent studies on the subject give mixed results. GitHub's experiments showed a 55% productivity gain for specific tasks such as writing an HTTP server from scratch. Other studies, including from METR and independent labs, recorded considerably more modest numbers or warned that gains in coding speed are often offset by more time spent reviewing and debugging AI-generated code. The reality depends heavily on the type of task, the team's experience level and how well the workflow around the tools is built.
New-generation AI agents are a separate problem. Early tools like Copilot worked as advanced autocomplete, but the agents of 2025-2026 claim to carry out entire tasks autonomously: from writing code to creating PRs and passing part of the CI/CD pipeline. That raises the stakes: if you cannot measure the ROI of a basic AI assistant, how will you evaluate the results of a semi-autonomous agent?
The main takeaway is simple but inconvenient for the market: engineering leaders should stop measuring usage and start designing real experiments with measurable outcomes before signing six-figure contracts for AI tools. Define metrics in advance: cycle time, defect rate, PR review time, onboarding time for new developers. Compare teams with and without the tool rather than just tracking general "satisfaction." Vendors will not teach you this, because they have no incentive to. But the ability to ask the uncomfortable question is what separates technical leaders who genuinely improve their teams' work from those who merely buy a feeling of progress.
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Kimi scores 96.2% on a 1C database analytics test and emerges as a fallback if Claude access is blocked
- Nov 1, 2026OpenAI Rewrites GPT Behavior Rules: Five Values and a Chain of Command
- Nov 1, 2026Google admits AI Mode cuts search revenue, shares fall 15%
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.