PostgreSQL at OpenAI: How to Scale a Database for ChatGPT
OpenAI has shared its experience scaling PostgreSQL to support ChatGPT. The team used replication, caching, rate limiting and workload isolation to reach millions of queries per second. This piece looks at the architecture and the decisions behind it.
AI-processed from OpenAI Blog; edited by Hamidun News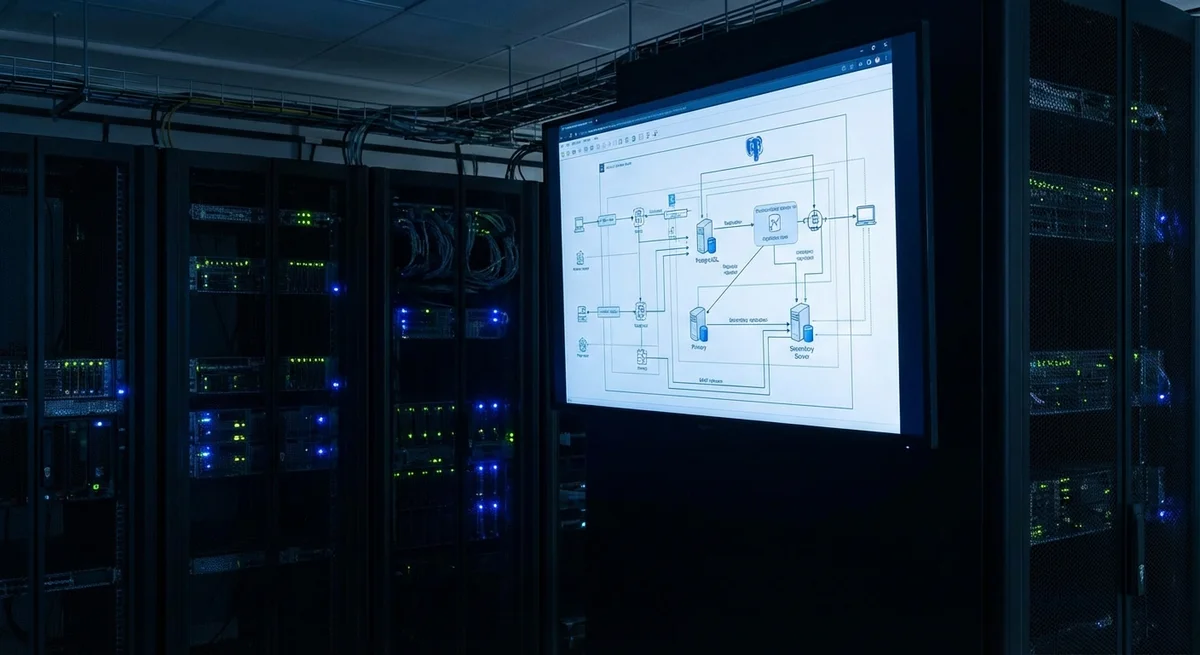
When ChatGPT took off, the OpenAI team faced a serious challenge: keeping the database underpinning everything, PostgreSQL, stable and fast. The system had to serve hundreds of millions of users and process millions of queries per second. Solving that took more than adding hardware. It required a deep rethink of the architecture and a range of engineering tricks.
Despite its maturity and reliability, PostgreSQL was not originally designed for such extreme loads. Traditional approaches such as vertical scaling (adding power to a single server) quickly hit a ceiling. It became clear that a horizontal approach was needed: spreading the load across many servers. OpenAI chose replication, creating many read-only copies of the database. This took significant pressure off the primary server and raised overall throughput.
Replication, however, is only part of the solution. For further optimization, the team used caching, which keeps the most frequently requested data in memory so the database is not hit on every request. The team also introduced rate limiting, which prevented the system from being overloaded during sudden traffic spikes. Finally, workload isolation played an important role: different types of queries were split across different servers to avoid conflicts and give priority to the most important operations.
These methods let OpenAI not only handle the current load but also build a scalable architecture ready for further growth. It is an important precedent for the whole industry, showing that even mature technologies such as PostgreSQL can be used successfully to support the most demanding AI applications. OpenAI's experience shows the value of a comprehensive approach that combines replication, caching, rate limiting and workload isolation.
The implications reach well beyond OpenAI. Other companies that work with big data and heavy loads can use these practices to optimize their own systems. This is especially relevant for e-commerce platforms, social networks and other services that need instant access to large volumes of information. The experience may also spur further development of PostgreSQL and other databases aimed at better scalability and performance.
In conclusion, OpenAI's success in scaling PostgreSQL is not just a technical achievement but an important lesson for the whole industry. It shows that the right approach to architecture and optimization can allow even mature technologies to handle the most difficult tasks. This opens up new possibilities for AI and other fields that require processing large amounts of data.
- Nov 2, 2026NC State's AICG Framework Cuts MAE by 50.3% on Math Answer Grading
- Nov 2, 2026We Audited 929 Automations at Alpina: What Corporate AI Training Should Look Like in 2026
- Nov 2, 2026I Interrogated 6 AI Models About Myself Through a Procurement Manager's Eyes: Amazon, Esoterica, 'Telo Hudelo' and 5 Holes We Closed in a Day
- Nov 2, 2026TJ Digital: 23% of AI-cited pages open with a direct answer, versus 14% of uncited ones
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.