AI Models in a Rut: Why ChatGPT, Claude and Gemini Think Alike
Ask any chatbot for a random number between 1 and 10 and you will almost certainly get 7. It is a symptom of a systemic problem: all the major LLMs were trained on similar data and lean toward "groupthink." Researchers have documented the pattern in Claude, ChatGPT and Gemini. One startup is developing methods to break this consensus so that models give genuinely different answers.
AI-processed from MIT Technology Review; edited by Hamidun News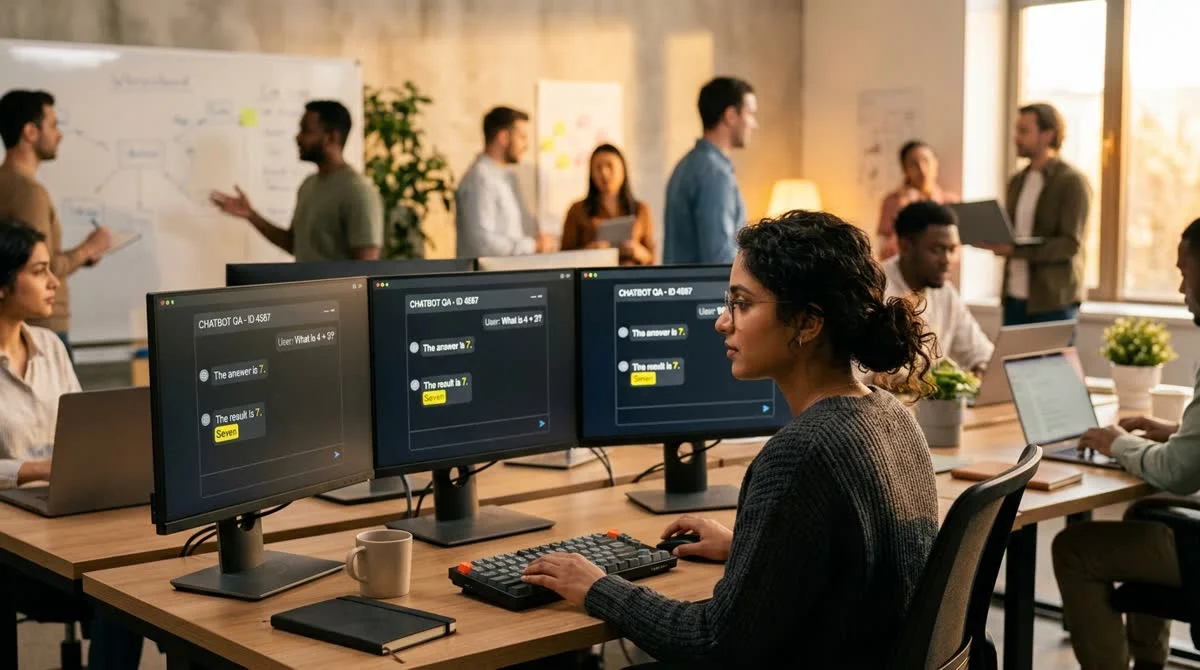
ChatGPT, Claude and Gemini give equally predictable answers to similar prompts. On July 1, 2026, MIT Technology Review described this as systemic "groupthink" among language models and reported on a startup developing ways to overcome it.
The number test: why isn't this a coincidence?
Ask any popular chatbot for a random number between 1 and 10 and you will almost certainly get 7. Ask again and you will hear 3 or 4, then 8 or 9. The pattern repeats with striking consistency across models from different companies.
The explanation is simple: all the major LLMs were trained on similar web corpora, where "7" appears more often than other numbers as an answer to this question, because people themselves call seven the "most random" number. Reinforcement learning fine-tuning (RLHF) further rewards "safe" and expected answers, the ones that more often earn high ratings from human raters. The models are, quite literally, trained to give the predictable answer.
- Seven as the "random" number is a textbook example of LLM templating
- The pattern shows up in Claude (Anthropic), ChatGPT (OpenAI) and Gemini (Google DeepMind)
- The cause is overlapping training data and similar RLHF procedures at all the major labs
Where groupthink does real harm
Numbers are only a visible symptom. In real tasks the problem is bigger: models repeat the same cultural clichés, phrase strategic recommendations in similar ways and suggest similar marketing solutions. When a company uses several LLMs to "diversify perspectives," it often gets reworded versions of the same opinion, with an illusion of independence.
"We have built an ecosystem in which all the models see the world the same way, because they read the same things,"
MIT Technology Review states.
The problem is sharpest where originality matters: generating scientific hypotheses, producing unconventional content, assessing non-trivial risks. In such cases, "independent verification" through several LLMs gives the illusion of diversity, but not diversity itself.
What the startup proposes
MIT Technology Review describes a startup focused on methods for overcoming "template thinking" in language models. The exact architecture of the solution has not been disclosed. Meanwhile, the industry is discussing several approaches to the problem:
- Training on more diverse data, deliberately including niche viewpoints
- Controlled stochasticity during fine-tuning, rewarding variability as an explicit goal
- Ensemble systems in which several models with different "biases" debate each other
- Response-diversity metrics as a mandatory part of evals, alongside accuracy and safety
What this means
If methods for overcoming "group consensus" manage to set a new industry standard, it will change how we evaluate AI systems: diversity and independence of answers will become measurable requirements, just like accuracy or safety. For enterprise users, this opens the possibility of getting genuinely different perspectives from AI, rather than a statistically averaged view in different wording.
Why do ChatGPT, Claude and Gemini give the same answers?
MIT Technology Review identified a systematic phenomenon it calls neural-network "groupthink": the models give equally predictable answers to similar prompts, even when asked to be random.
Can identical AI answers be fixed?
The startup described in the article is developing ways to overcome this phenomenon in language models.
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Kimi scores 96.2% on a 1C database analytics test and emerges as a fallback if Claude access is blocked
- Nov 1, 2026OpenAI Rewrites GPT Behavior Rules: Five Values and a Chain of Command
- Nov 1, 2026Google admits AI Mode cuts search revenue, shares fall 15%
Key Questions Answered
The number test: why isn't this a coincidence?
Ask any popular chatbot for a random number between 1 and 10 and you will almost certainly get 7. Ask again and you will hear 3 or 4, then 8 or 9. The pattern repeats with striking consistency across models from different companies. The explanation is simple: all the major LLMs were trained on similar web corpora, where "7" appears more often than other numbers as an answer to this question, because people themselves call seven the "most random" number. Reinforcement learning fine-tuning (RLHF) further rewards "safe" and expected answers, the ones that more often earn high
Why do ChatGPT, Claude and Gemini give the same answers?
MIT Technology Review identified a systematic phenomenon it calls neural-network "groupthink": the models give equally predictable answers to similar prompts, even when asked to be random.
Can identical AI answers be fixed?
The startup described in the article is developing ways to overcome this phenomenon in language models.
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.