New Computer Boosts Agent Memory Retrieval Accuracy by 50% with LangSmith
New Computer is a startup building a personal AI assistant with long-term memory. The team raised retrieval accuracy over that memory by 50% using the LangSmith observability tool. The key was the test comparison mode, which helped catch regressions before changes reached production and made it quick to adjust prompts. The result: the agent is twice as reliable at finding the right context from past conversations.
AI-processed from LangChain Blog; edited by Hamidun News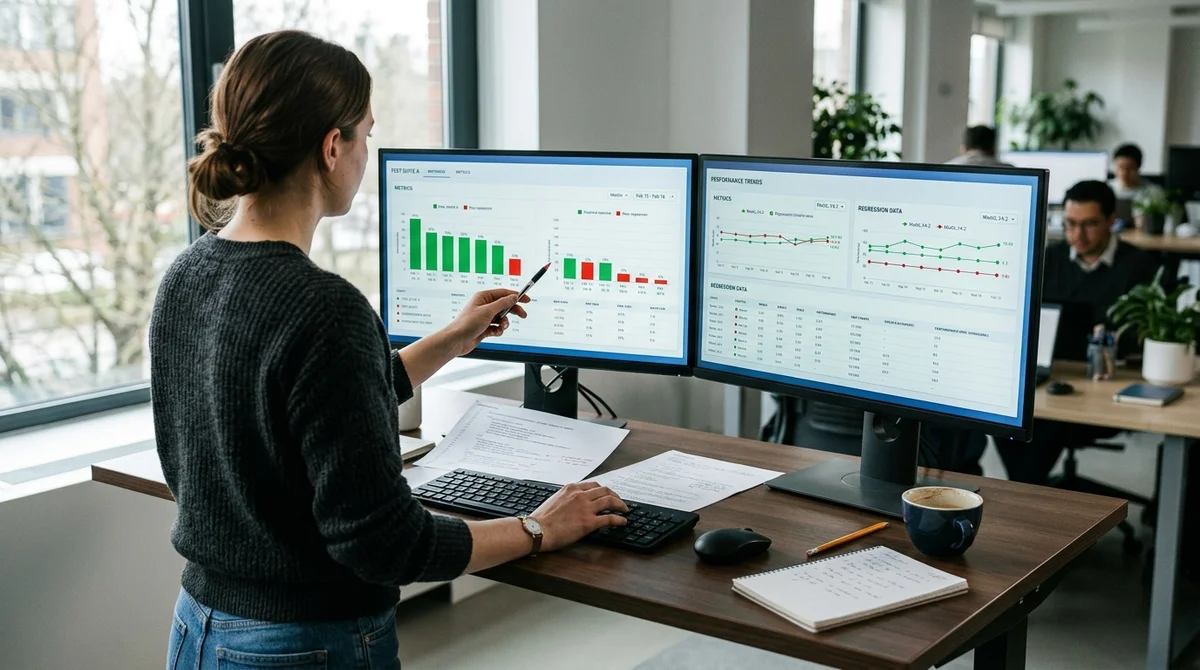
Startup New Computer raised the retrieval accuracy of its AI agent's memory system by 50% using the LangSmith observability tool. The success rests not on a new architecture but on a disciplined methodology for testing prompts.
Why agents need long-term memory
New Computer's product is a personal AI assistant that genuinely remembers the user: their preferences, past conversations, habits and life context. This fundamentally sets the assistant apart from an ordinary chatbot, which starts from a blank slate every time.
Implementing long-term memory is technically nontrivial. You cannot simply save everything that was said and send it into the model's context every time: the volume of data grows, and the cost of requests makes this approach unviable. Instead, memory systems are built on retrieval: only relevant fragments are pulled from the accumulated database.
This is where the recall metric comes in: how often the system finds exactly the memories needed right now. Low recall means the agent "fails to remember" important details even when they are in the database. For a personal assistant, this is a critical problem.
What LangSmith delivered
LangSmith is an observability tool from LangChain: it logs every step of an LLM application's operation, lets you create test datasets and compare versions of the system in a clear interface. The New Computer team built an iterative process around several features:
- Comparison View — a visual side-by-side of two runs: you can see which scenarios improved and which degraded
- Regression tracking — automatic detection of cases where the new version of the system performs worse than the previous one
- Fast iteration loop — change the prompt → run the test → compare results → accept or roll back
- Conversation logging — the full history of requests helped identify patterns in which memory retrieval failed
The main insight: without structured comparison, regressions stayed invisible. When a prompt improved some scenarios, it quietly broke others. LangSmith made those breakages visible immediately, before changes reached production.
From intuition to measurable results
Before adopting LangSmith, the team worked on a "we tried it, it seems better" basis. Subjective judgments did not allow them to compare versions with confidence: too many variables, too little measurable data.
After moving to comparison testing, every prompt change went through a set of test scenarios. Results were recorded and compared with the previous version, and changes were accepted only after a confirmed improvement. Regression turned from a random "something broke" into a diagnosable, manageable problem.
The result is a 50% increase in recall: the agent became one and a half times more likely to find relevant memories from past conversations. For a personal assistant whose value is measured by the quality of its memory, this is a fundamental product improvement.
What this means
The New Computer case shows that the quality of an AI product today is determined not only by architecture or the choice of base model, but also by the observability system. Teams that see their regressions in real time iterate faster, and this translates directly into metrics.
Tools like LangSmith move LLM application development from a "seems to work" mode to one of measurable, reproducible improvements.
- Nov 1, 2026Google's StreamVibe video agent beats other models by 10.7% on response timing and quality
- Nov 1, 2026New test catches hidden AI agent collusion by measuring how a partner reacts to a paraphrase
- Nov 1, 2026Illinois compiled 12 151 open problems and tested whether AI can solve them
- Oct 31, 2026AI engineer writes a single reward function for agent teams: win rate climbs from 51% to 90%
Key Questions Answered
Why agents need long-term memory?
New Computer's product is a personal AI assistant that genuinely remembers the user: their preferences, past conversations, habits and life context. This fundamentally sets the assistant apart from an ordinary chatbot, which starts from a blank slate every time. Implementing long-term memory is technically nontrivial. You cannot simply save everything that was said and send it into the model's context every time: the volume of data grows, and the cost of requests makes this approach unviable. Instead, memory systems are built on retrieval: only relevant fragments are pulled
What LangSmith delivered?
LangSmith is an observability tool from LangChain: it logs every step of an LLM application's operation, lets you create test datasets and compare versions of the system in a clear interface. The New Computer team built an iterative process around several features: Comparison View — a visual side-by-side of two runs: you can see which scenarios improved and which degraded Regression tracking — automatic detection of cases where the new version of the system performs worse than the previous one Fast iteration loop — change the prompt → run the test → compare results → accept
What are the key details on From intuition to measurable results?
Before adopting LangSmith, the team worked on a "we tried it, it seems better" basis. Subjective judgments did not allow them to compare versions with confidence: too many variables, too little measurable data. After moving to comparison testing, every prompt change went through a set of test scenarios. Results were recorded and compared with the previous version, and changes were accepted only after a confirmed improvement. Regression turned from a random "something broke" into a diagnosable, manageable problem. The result is a 50% increase in recall: the agent became one
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.