AWS shows how data mesh can become the foundation for agentic AI in production
AWS has published a guide to building a data mesh on its platform as a reliable base for agentic AI in production. The premise: agents cannot work reliably without governed access to data. AWS proposes a serverless stack of S3, Glue, Lake Formation and Athena, with domain-level role-based access, full auditing and data contracts for every AI agent.
AI-processed from AWS Machine Learning Blog; edited by Hamidun News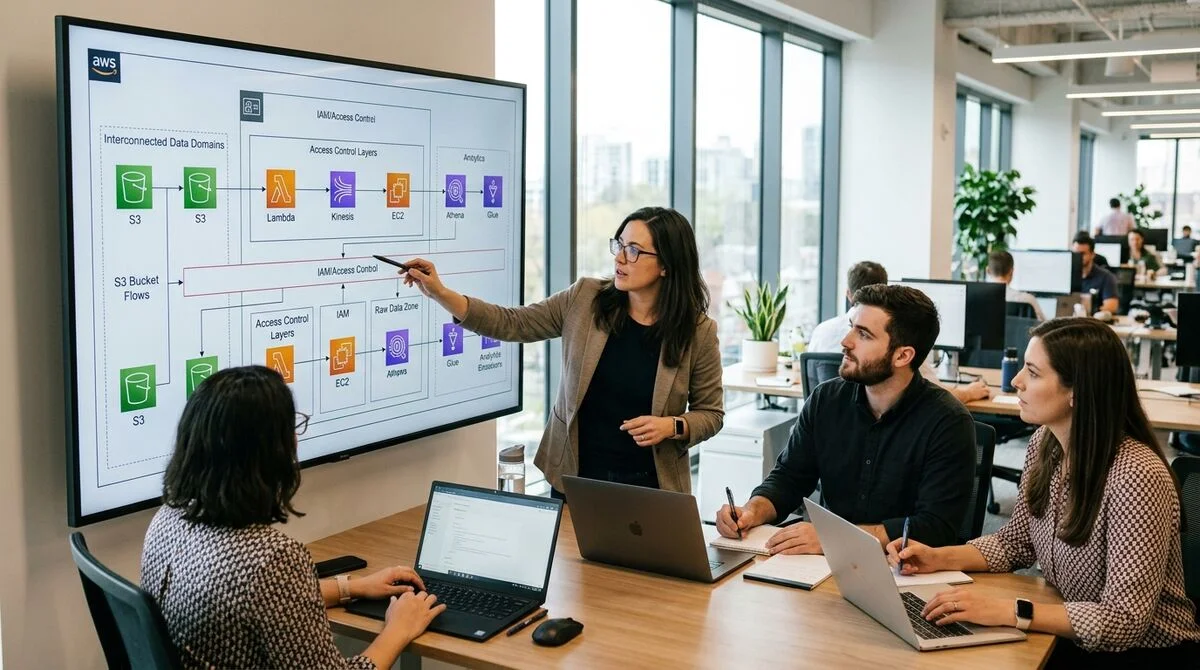
AWS has published a detailed technical guide to building a governed serverless data mesh, an architecture that gives agentic AI a reliable, secure and scalable foundation for production work.
Why agents need a data mesh
Agentic AI differs fundamentally from chatbots: it builds chains of actions on its own, calls tools and makes decisions without a human in the loop. To do this reliably, an agent must get up-to-date enterprise data in real time, and strictly within security policies.
The problem is that enterprise data is traditionally scattered across dozens of systems, teams and formats. Centralized data warehouses and data lakes solve part of the problem but create a bottleneck: data goes stale, schemas drift apart, and a single engineering team cannot keep up with requests from every department.
Data mesh takes a different approach: each domain (finance, marketing, logistics) owns its data and publishes it as a "product", with documentation, clear schemas and access contracts. An AI agent connects to such a product directly, with no intermediaries.
Architecture on AWS
AWS offers a serverless stack that makes it possible to implement a data mesh without managing servers:
- Amazon S3: decentralized storage; each domain keeps its data in separate buckets
- AWS Glue Data Catalog: a single catalog of schemas and metadata for all domains
- AWS Lake Formation: access control at the table, column and row level
- Amazon Athena: serverless SQL queries over data in S3 without additional ETL pipelines
- AWS IAM: a role-based model in which each agent gets the minimum permissions it needs
The key point: the agent does not need to know where the data physically lives. It addresses a logical product through the Glue catalog, not S3 buckets directly. This lets teams move and restructure data without changing the interface for agents.
In practice the cycle looks like this: the agent receives an IAM role, Lake Formation checks permissions on every request, Athena runs the SQL, and the result returns to the agent. Everything is serverless, and every action is auditable.
Security and control
Agentic AI is unpredictable: it can generate a query that overloads the system, or try to read data outside its own domain. AWS addresses this at several levels.
Lake Formation policies block any query outside the permitted scope, even if the agent technically has access to S3. CloudTrail keeps a full audit log of every action. Athena quotas cap the amount of data scanned per query, which protects against accidental or deliberate overload.
Another important detail is data semantics. The Glue Data Catalog stores not only schemas but also field descriptions: the agent understands the meaning of what it reads, rather than just receiving a set of bytes with no context. Schema versioning ensures that a structural change in one domain will not break the agents working with that product.
What this means
Data mesh is ceasing to be a theoretical concept and is becoming a practical requirement for anyone building production AI. Companies without governed data access will end up with agents that are either unreliable or unsafe, and more often both at once.
AWS offers a ready-made serverless stack that covers most tasks out of the box.
- Oct 31, 2026Worldwide Express hands disputed invoices to AI agents and cuts unresolved disputes by 75%
- Oct 30, 2026AWS gives coding agents a live site preview straight from an isolated session
- Oct 30, 2026MoEngage Opens 400 Private APIs to AI Agents Through AgentCore Gateway, Without Building Its Own MCP Servers
- Oct 29, 2026NVIDIA Nemotron 3.5 Super VL: 120B Parameters, 12B Active, Running on AWS
Key Questions Answered
Why agents need a data mesh?
Agentic AI differs fundamentally from chatbots: it builds chains of actions on its own, calls tools and makes decisions without a human in the loop. To do this reliably, an agent must get up-to-date enterprise data in real time, and strictly within security policies. The problem is that enterprise data is traditionally scattered across dozens of systems, teams and formats. Centralized data warehouses and data lakes solve part of the problem but create a bottleneck: data goes stale, schemas drift apart, and a single engineering team cannot keep up with requests from every de
What are the key details on Architecture on AWS?
AWS offers a serverless stack that makes it possible to implement a data mesh without managing servers: Amazon S3: decentralized storage; each domain keeps its data in separate buckets AWS Glue Data Catalog: a single catalog of schemas and metadata for all domains AWS Lake Formation: access control at the table, column and row level Amazon Athena: serverless SQL queries over data in S3 without additional ETL pipelines AWS IAM: a role-based model in which each agent gets the minimum permissions it needs The key point: the agent does not need to know where the data physically
What are the key details on Security and control?
Agentic AI is unpredictable: it can generate a query that overloads the system, or try to read data outside its own domain. AWS addresses this at several levels. Lake Formation policies block any query outside the permitted scope, even if the agent technically has access to S3. CloudTrail keeps a full audit log of every action. Athena quotas cap the amount of data scanned per query, which protects against accidental or deliberate overload. Another important detail is data semantics. The Glue Data Catalog stores not only schemas but also field descriptions: the agent underst
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.