A Context Window Is Not Memory: What AI Agent Developers Need to Understand
AI agent developers often mistake a large context window for long-term memory, and that is a fundamental architectural error. Context disappears after each session, while real memory requires a separate system: RAG, compression or episodic storage. An agent with a 2-million-token window will still forget the user the next day.
AI-processed from Machine Learning Mastery; edited by Hamidun News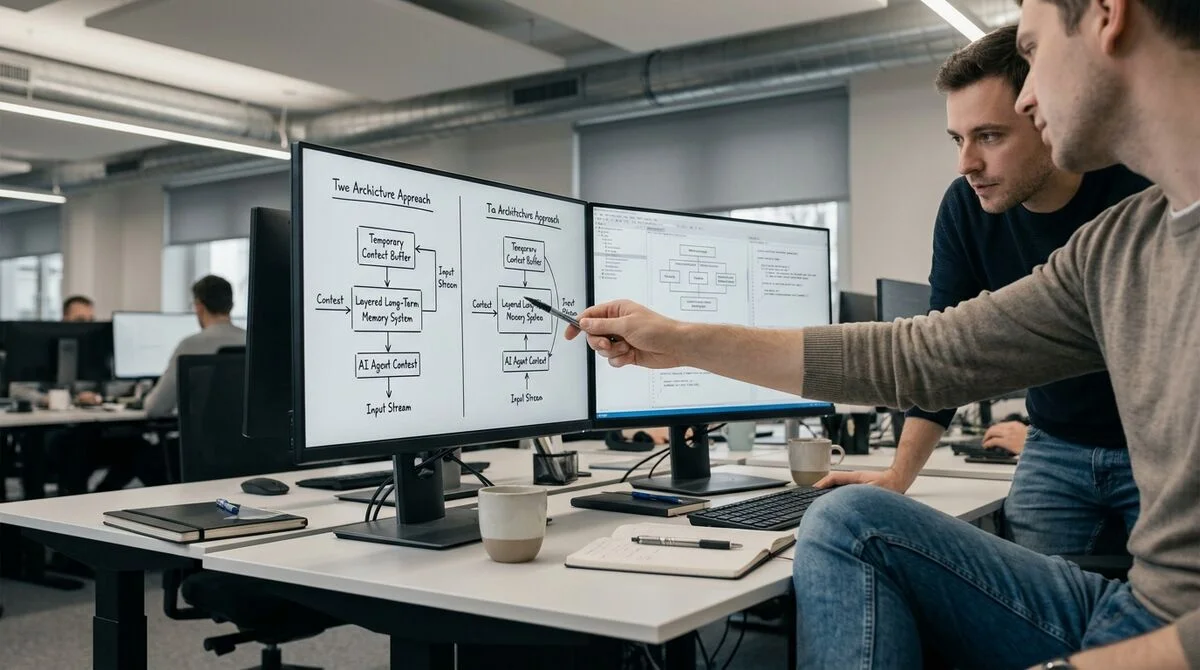
A large context window is a popular argument when choosing a model for an AI agent. But it solves a different problem from long-term memory. Developers who confuse the two build agents with a fundamental architectural flaw.
Context is a desk, not an archive
The context window works like a computer's RAM: everything in it is something the agent "sees" right now and can use in its answer. When the session ends, the contents vanish without a trace.
Long-term memory is something fundamentally different: knowledge persists between sessions, is indexed and is retrieved when needed. It is a separate system with its own architecture, designed independently of the choice of model.
An agent with a 2-million-token window still forgets the user the next day. A bigger context only postpones the collision with the problem; it does not eliminate it.
Five techniques for real memory
AI agent developers use several approaches to manage knowledge between sessions:
- RAG (Retrieval-Augmented Generation): the agent queries an external knowledge base only when needed, instead of keeping everything in the window. It suits large document corpora.
- Compression: a long conversation history is condensed into a short summary that takes 10–20 times fewer tokens.
- Episodic memory: key facts about the user or task are saved to structured storage and loaded at the start of the next session.
- Summarization chains: large documents are converted into digests before they reach the agent's context.
- Selective storage: an orchestrator decides what is worth saving, what to compress and what to discard entirely.
Each tool solves its own task. A support chatbot needs episodic memory; an analyst agent working over a document corpus needs RAG.
The problem with a full context
There is another reason not to rely on a large window alone: the "lost in the middle" phenomenon. Research shows that models handle information in the middle of a long context worse, and answer quality drops even when the space is technically available.
The practical takeaway: even if the context can technically hold 500 pages of text, you should not pile everything in. Selectivity and compression give better answers than brute-force filling.
"The context window is a desk.
You don't pile everything you own on it. You pull out only what you need right now."
Memory architecture for production
Teams building agents for real users should design the memory system separately from the choice of model. Key questions at the design stage: what needs to be remembered between sessions, what the TTL is for each type of information, how the agent decides what to save, and where to store it: in a vector database, a relational one or a knowledge graph.
Without answers to these questions, the agent remains a disposable tool: the user has to explain the context again on every run. This matters most in support, education and medicine, anywhere knowledge about the user builds up over weeks.
What this means
Choosing a model with a large context is tactics. A memory system is architecture. Developers who confuse the two will find the problem not in the prototype but in the product, when users are already unhappy. Design memory from day one.
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Adobe's EditAgent judge picks a usable edit 81.3% of the time, versus 74.8% for EditScore
- Nov 1, 202616 models tested on 7 search tools: Exa averaged 10.5 out of 14, SearXNG about 3
- Nov 1, 2026Google's StreamVibe video agent beats other models by 10.7% on response timing and quality
Key Questions Answered
What are the key details on Context is a desk, not an archive?
The context window works like a computer's RAM: everything in it is something the agent "sees" right now and can use in its answer. When the session ends, the contents vanish without a trace. Long-term memory is something fundamentally different: knowledge persists between sessions, is indexed and is retrieved when needed. It is a separate system with its own architecture, designed independently of the choice of model. An agent with a 2-million-token window still forgets the user the next day. A bigger context only postpones the collision with the problem; it does not elimi
What are the key details on Five techniques for real memory?
AI agent developers use several approaches to manage knowledge between sessions: RAG (Retrieval-Augmented Generation): the agent queries an external knowledge base only when needed, instead of keeping everything in the window. It suits large document corpora. Compression: a long conversation history is condensed into a short summary that takes 10–20 times fewer tokens. Episodic memory: key facts about the user or task are saved to structured storage and loaded at the start of the next session. Summarization chains: large documents are converted into digests before they reac
What are the key details on The problem with a full context?
There is another reason not to rely on a large window alone: the "lost in the middle" phenomenon. Research shows that models handle information in the middle of a long context worse, and answer quality drops even when the space is technically available. The practical takeaway: even if the context can technically hold 500 pages of text, you should not pile everything in. Selectivity and compression give better answers than brute-force filling. "The context window is a desk. You don't pile everything you own on it. You pull out only what you need right now."
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.