Clustering Text Without Labels: LLM Embeddings and HDBSCAN, per Machine Learning Mastery
Language models do more than answer questions in a chat: they turn text into numerical vectors that can be used to find topic groups automatically. Machine Learning Mastery has published a guide on combining LLM embeddings with the HDBSCAN algorithm to cluster thousands of documents without labels. The pipeline: embedding → UMAP (dimensionality reduction) → HDBSCAN → automatic topic labels.
AI-processed from Machine Learning Mastery; edited by Hamidun News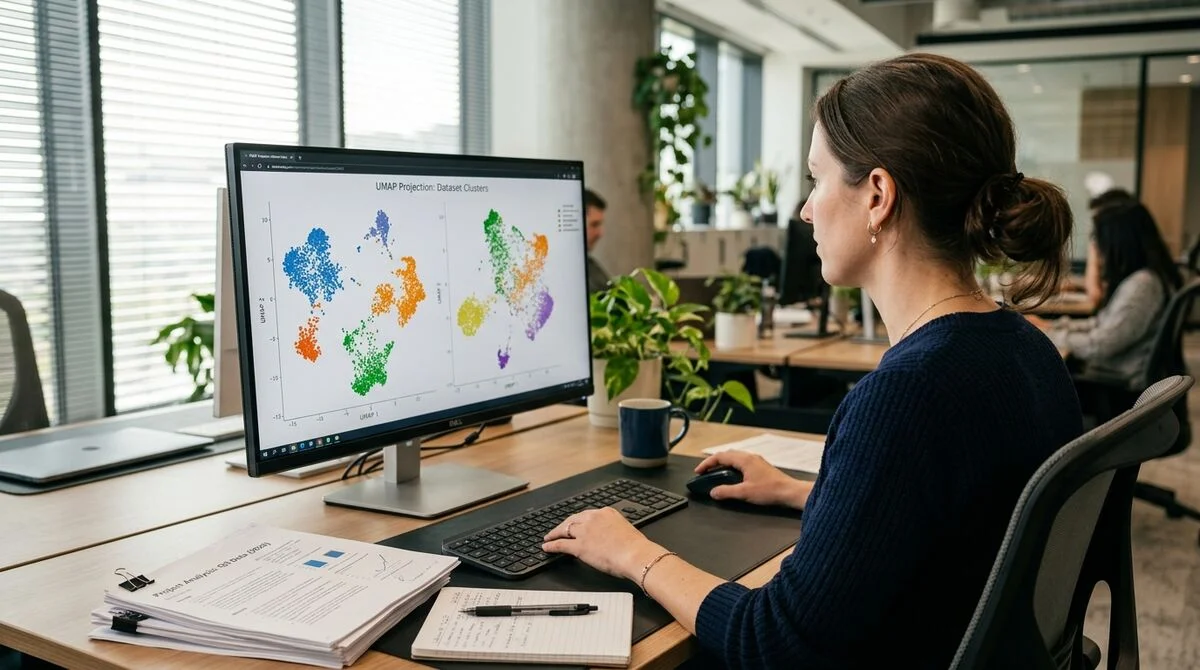
LLM embeddings have taken tasks involving unstructured text far beyond chat interfaces. Machine Learning Mastery has published a practical guide on combining language-model vector representations with the HDBSCAN algorithm to automatically find topic groups in text collections, with no manual labeling or prior knowledge of the data's structure.
Why embeddings change the rules of the game
Language models can convert text into high-dimensional vectors. These are numerical representations in which semantically similar fragments end up geometrically close together. "The customer is unhappy with the price" and "too expensive for me" will be neighbors in the multidimensional space, while "problem with delivery" will land in a completely different region. That is what makes embeddings an ideal input for clustering: the system takes meaning into account, not keyword overlap. Synonym dictionaries and rules are no longer needed.
Popular models for producing embeddings include OpenAI `text-embedding-3-small`, Cohere Embed v3, and open-source sentence-transformers, which run locally with no API costs. A typical embedding has 768–3072 dimensions, which is too many for direct clustering. Before HDBSCAN, it is standard practice to apply UMAP, which compresses the space to 5–50 dimensions. Without this step, the algorithm runs into the "curse of dimensionality": in a high-dimensional space all points look roughly equally far apart, and clusters do not form.
HDBSCAN versus standard methods
Most clustering courses start with K-means. The problem: it requires you to set the number of clusters in advance, which is impossible when the structure of the data is unknown. HDBSCAN (Hierarchical Density-Based Spatial Clustering of Applications with Noise) approaches the task differently:
- Does not require setting the number of clusters in advance
- Automatically flags "noise" points: texts that fit into no group
- Handles clusters of different sizes and densities correctly
- Scales to tens of thousands of documents
- Produces a cluster hierarchy with adjustable granularity
The full pipeline: embeddings → dimensionality reduction via UMAP → HDBSCAN → cluster labels. The whole thing takes a few dozen lines of Python using the `sentence-transformers`, `umap-learn` and `hdbscan` libraries. To interpret the topics found, it is enough to pass a few examples from each group back to an LLM and ask it to come up with a name. The loop closes from language model to statistics and back again.
Use without a training set
The main advantage of this combination is that it needs no labeling at all. There is no need to agree on categories, hire annotators or build a training set. A single pipeline discovers the structure on its own.
"The current era of generative AI is focused on chat interfaces, but the capabilities of language models go far beyond that," write the authors at
Machine Learning Mastery.
Typical scenarios include clustering thousands of support requests, automatically categorizing news streams, grouping product reviews, analyzing open-ended survey questions, and detecting anomalous patterns in logs. Results appear within minutes, with no prior labeling.
The approach is especially valuable for fast-changing data: new topics are discovered automatically, so there is no need to manually add classes to a classifier every time the subject domain shifts.
What this means
Combining LLM embeddings with HDBSCAN gives teams a ready-made tool for structuring large text datasets without supervision. Tasks that once required weeks of manual work or expensive labeling can now be handled by a small script. For teams working with user feedback, media monitoring or content analytics, this means direct resource savings, and a way to extract insights from data that used to sit idle.
- Nov 2, 2026Meta's Muse assistant keeps dossiers on loved ones and gets root on Ubuntu by default
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Kimi scores 96.2% on a 1C database analytics test and emerges as a fallback if Claude access is blocked
- Nov 1, 2026OpenAI Rewrites GPT Behavior Rules: Five Values and a Chain of Command
Key Questions Answered
Why embeddings change the rules of the game?
Language models can convert text into high-dimensional vectors. These are numerical representations in which semantically similar fragments end up geometrically close together. "The customer is unhappy with the price" and "too expensive for me" will be neighbors in the multidimensional space, while "problem with delivery" will land in a completely different region. That is what makes embeddings an ideal input for clustering: the system takes meaning into account, not keyword overlap. Synonym dictionaries and rules are no longer needed. Popular models for producing embedding
What are the key details on HDBSCAN versus standard methods?
Most clustering courses start with K-means. The problem: it requires you to set the number of clusters in advance, which is impossible when the structure of the data is unknown. HDBSCAN (Hierarchical Density-Based Spatial Clustering of Applications with Noise) approaches the task differently: Does not require setting the number of clusters in advance Automatically flags "noise" points: texts that fit into no group Handles clusters of different sizes and densities correctly Scales to tens of thousands of documents Produces a cluster hierarchy with adjustable granularity The
What are the key details on Use without a training set?
The main advantage of this combination is that it needs no labeling at all. There is no need to agree on categories, hire annotators or build a training set. A single pipeline discovers the structure on its own. "The current era of generative AI is focused on chat interfaces, but the capabilities of language models go far beyond that," write the authors at Machine Learning Mastery. Typical scenarios include clustering thousands of support requests, automatically categorizing news streams, grouping product reviews, analyzing open-ended survey questions, and detecting anomalo
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.