AI2's olmo-eval Brings Continuous Model Evaluation Into the Training Loop
AllenAI has open-sourced olmo-eval, an evaluation harness for language models built directly into the training process. Instead of testing only at the end, it evaluates at every checkpoint, so researchers can see in real time how a change to the dataset or hyperparameters affects benchmark results. The tool is published on Hugging Face and is aimed at researchers who want evaluation to be part of development, not an afterthought.
AI-processed from Hugging Face Blog; edited by Hamidun News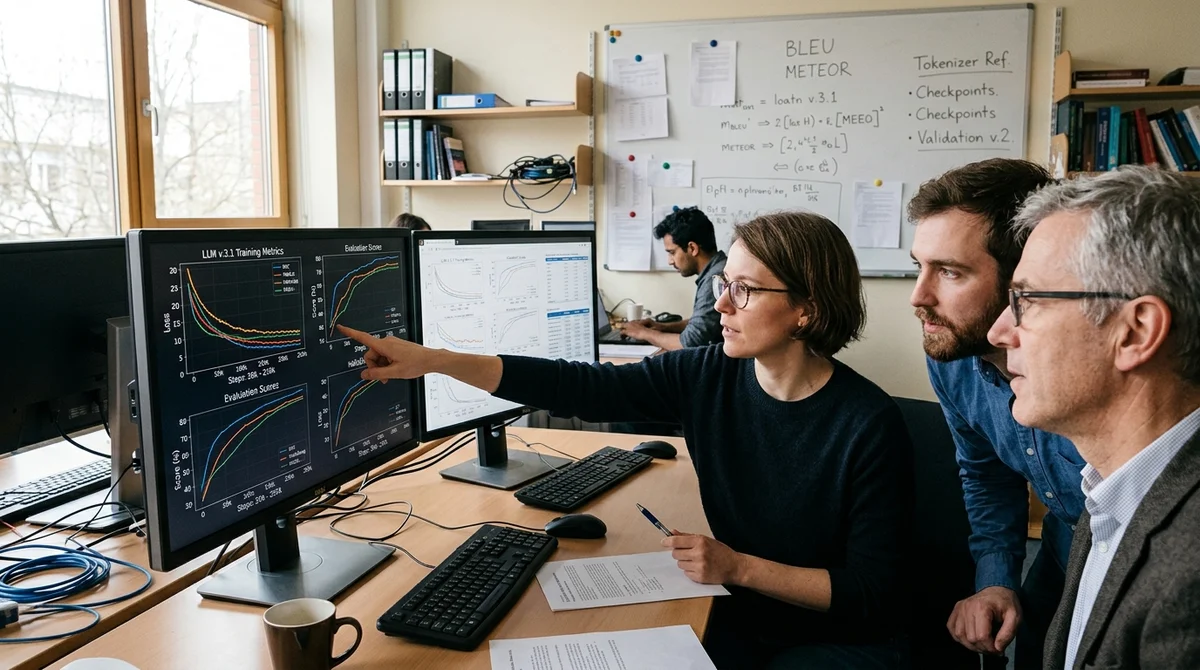
AllenAI has launched olmo-eval, an AI tool for evaluating language models during training itself.
What is olmo-eval and where can you get it?
olmo-eval is an open toolkit from AllenAI for evaluating language models, built into the training loop. The project is available on Hugging Face and is aimed at researchers.
Why evaluate models during training?
The standard process: a model trains for several days or weeks, then gets evaluated on benchmarks (ARC, HellaSwag, MMLU). olmo-eval lets researchers watch how model quality changes during training, rather than getting only a final result.
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Pika Labs releases open video model H3 Flex: 6 steps instead of 50
- Nov 1, 2026Hugging Face's BERT Tokenizer Gets a 50x Speedup by Skipping Needless Work on ASCII
- Nov 1, 2026Illinois compiled 12 151 open problems and tested whether AI can solve them
Key Questions Answered
What is olmo-eval and where can you get it?
olmo-eval is an open toolkit from AllenAI for evaluating language models, built into the training loop. The project is available on Hugging Face and is aimed at researchers.
Why evaluate models during training?
The standard process: a model trains for several days or weeks, then gets evaluated on benchmarks (ARC, HellaSwag, MMLU). olmo-eval lets researchers watch how model quality changes during training, rather than getting only a final result.
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.