Mentorpiece launches free course on non-functional testing of AI applications
Mentorpiece has opened a free course on non-functional testing of AI applications. The program covers testing for cost, traceability, reliability and privacy, as well as checks for AI agents, RAG and fine-tuned models. The authors walk through real cases: one model can be both more accurate and many times cheaper than another, and under heavy load services start hitting 429 errors or returning empty responses. It is a short on-ramp to AI-QA for ordinary testers.
AI-processed from Habr AI; edited by Hamidun News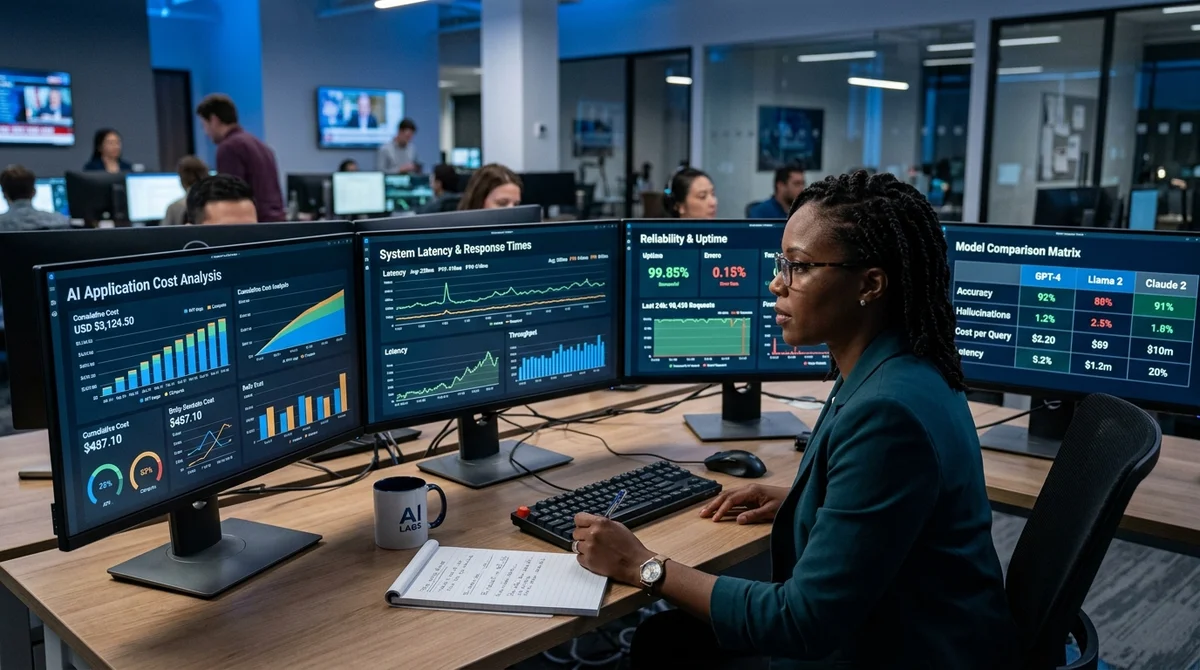
Mentorpiece has released a free introductory course on non-functional testing of AI applications. The authors start from a simple idea: for model-based products, answer quality is no longer enough, because price, latency, instability and the opacity of the models themselves break the end-user experience.
Why AI is harder
In classic development, non-functional checks are often postponed until release or even until after the first users arrive. With AI applications, that approach quickly hurts the product. Even if a scenario looks like it works in a demo, very different constraints can surface in production: erratic token costs, unstable latency, provider limits, empty responses or quality degradation on real data. For a team, these are no longer minor details but part of the basic check of whether a feature can be launched in the business at all.
Traceability is a separate problem. An AI model remains a black box even for the team that deployed it: one set of data goes in, an answer comes out, and the logic inside is hidden. The article illustrates this with the answer "42" from The Hitchhiker's Guide to the Galaxy: there is a result, but why it is what it is remains unclear. Without traceability testing, a product quickly starts producing output that is hard to explain, reproduce and improve.
Real-world cases
One of the most telling examples in the material is cost testing. A team compared two models for the role of primary model in an application: a popular model A and a lesser-known model B. In the test, model A produced 63% more errors than model B. Its input tokens also cost $75 per million, versus $3.75 for model B. In other words, the cheaper model turned out to be not a compromise but the better option on both price and quality.
"Model B is 20 times cheaper with much better accuracy."
The second case concerns reliability under load. One AI application used three models from three different providers at once. While several dozen automated tests ran in parallel, the system behaved normally. But once the count passed a hundred simultaneous tests, failures began: one model started regularly returning a 429 Too Many Requests error, and another returned empty output with no explicit error in about 10% of cases. To a user this looks like a random breakage; to QA it is a signal that load and reliability checks are mandatory here.
What the course covers
The Mentorpiece course is designed as an introduction for testers who have not yet worked with AI applications but want to quickly understand where the new risks lie. It does not try to bury the reader in the math of models. Instead, it gathers the main areas of testing that most often affect the launch and operation of AI features in a real product.
- cost testing and comparing models by price and errors
- traceability testing and black-box analysis
- checks of reliability, resilience and behavior under load
- tests for privacy and data leaks
- approaches to testing AI agents, RAG, fine-tuned models, data and LLM-as-a-Judge scenarios
The authors also raise the practical question of choosing a model. Their thesis is simple: public benchmarks cannot be trusted blindly, because a real product lives on its own data, with its own limits on budget, speed and acceptable error rate.
The course is free, and registration is needed only to save progress. Besides the Mentorpiece platform, it has also been posted on Stepik.
What this means
AI-QA is quickly ceasing to be a narrow specialty. Even teams that do not build their own models already have to test the behavior of external LLMs as part of the product: count the money, catch degradation, track failures and understand why the system answers the way it does. The free Mentorpiece course is an attempt to provide a basic map of this new territory, where non-functional testing is not an add-on but a condition for an AI service to work properly.
Key Questions Answered
Why AI is harder?
In classic development, non-functional checks are often postponed until release or even until after the first users arrive. With AI applications, that approach quickly hurts the product. Even if a scenario looks like it works in a demo, very different constraints can surface in production: erratic token costs, unstable latency, provider limits, empty responses or quality degradation on real data. For a team, these are no longer minor details but part of the basic check of whether a feature can be launched in the business at all. Traceability is a separate problem. An AI mod
What are the key details on Real-world cases?
One of the most telling examples in the material is cost testing. A team compared two models for the role of primary model in an application: a popular model A and a lesser-known model B. In the test, model A produced 63% more errors than model B. Its input tokens also cost $75 per million, versus $3.75 for model B. In other words, the cheaper model turned out to be not a compromise but the better option on both price and quality. "Model B is 20 times cheaper with much better accuracy." The second case concerns reliability under load. One AI application used three models fr
What the course covers?
The Mentorpiece course is designed as an introduction for testers who have not yet worked with AI applications but want to quickly understand where the new risks lie. It does not try to bury the reader in the math of models. Instead, it gathers the main areas of testing that most often affect the launch and operation of AI features in a real product. cost testing and comparing models by price and errors traceability testing and black-box analysis checks of reliability, resilience and behavior under load tests for privacy and data leaks approaches to testing AI agents, RAG,
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.