Why the Brain Is Hundreds of Millions of Times More Efficient Than GPT-4, and Where Neuromorphic Chips Are Heading
The human brain spends millions of times less energy per act of thought than today's LLMs, and the difference is not just about hardware. The key differences are analog computation, sparse activation, recurrence and local learning. Neuromorphic chips are already leaving the lab: SpiNNaker2, Akida and Xylo show where AI hardware may go in the next few years.
AI-processed from Habr AI; edited by Hamidun News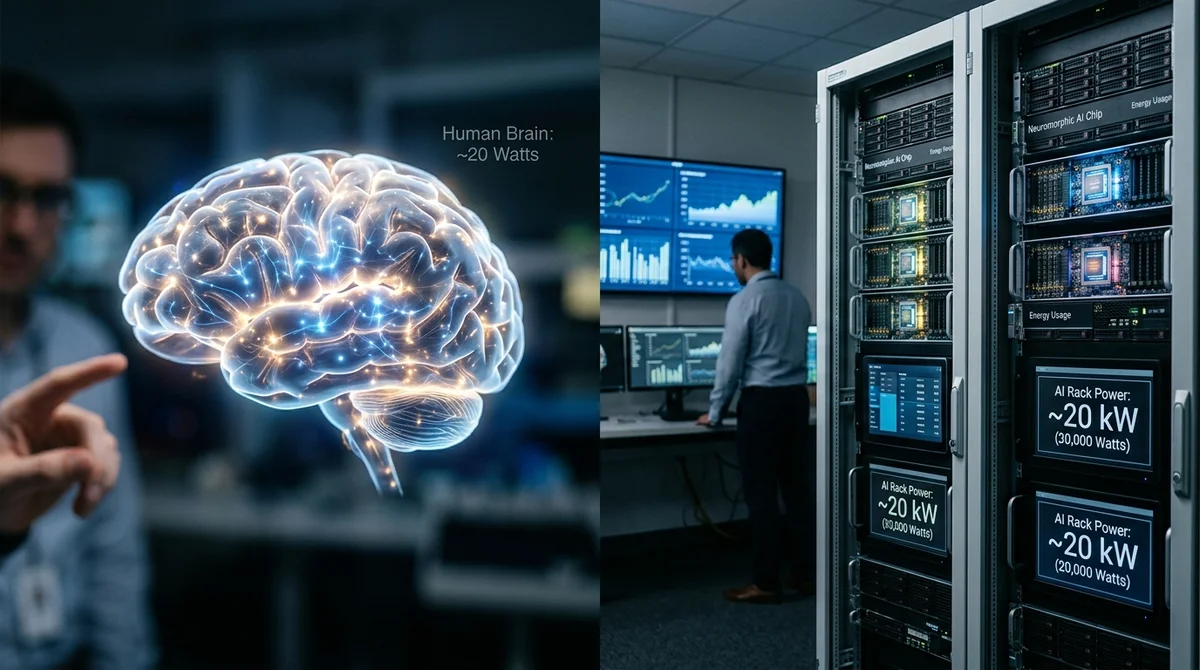
Comparing the human brain with modern LLMs reveals a fact that is uncomfortable for the AI industry: even the most powerful models remain extremely power-hungry. The brain runs on roughly 20 watts, while large language models can require kilowatts during inference and megawatts of power during training. If you look past marketing benchmarks and measure the cost of a single act of thought, the gap is colossal: biology still does the same work orders of magnitude more cheaply than silicon.
The article starts the comparison with basic numbers. The brain is estimated to perform about 10^16 synaptic operations per second on roughly 20 watts. Modern LLMs reach a comparable computational scale with GPUs and TPUs, but each operation costs far more. In energy per action, the brain operates in attojoules, while digital accelerators operate in picojoules and above.
The author also gives a more tangible example. To answer a simple question such as the difference between methane and ethane, the brain activates only a small fraction of its neurons and spends roughly a few tenths of a joule, whereas GPT-4 has to load a huge array of parameters and run an enormous volume of matrix operations. Framed this way, the gap can reach hundreds of millions of times.
The cause is not that engineers simply build poor hardware, but the principles of computation themselves. The brain works in analog: neurons and synapses operate on continuous gradients, membrane potentials and ionic currents. A single biological element both stores state and takes part in computation. LLMs work differently: data is represented in bits, computation is separated from memory, and every matrix operation breaks down into a long chain of digital switching events.
The brain's second advantage is recurrence and temporal dynamics. The same neuron is engaged repeatedly in processing a signal, and time becomes part of the computation. A transformer, by contrast, pushes every token through a fixed set of layers and pays for it with a huge number of parallel operations.
The third difference is sparsity. Only a small fraction of neurons in the brain is active at any moment, so the system does not waste energy switching on the entire network. An LLM engages huge arrays of weights at every step, even when the task is relatively simple.
The fourth factor is local learning. A biological system changes specific synapses where new experience occurred, rather than running global backpropagation through a giant network. The fifth is the physics of the substrate itself: ion channels and biochemical processes operate close to the thermodynamic minimum, whereas even advanced transistors switch with far greater losses.
Finally, the brain gets part of its structure for free: the visual cortex, hippocampus, cerebellum and other specialized blocks came to it as a result of evolution, while LLMs have to learn the structure of the world from scratch through massive datasets and very expensive training.
This does not mean large models have no future. The more reasonable conclusion is that the current transformer architecture has run into the energy price of its own convenience. The industry is already looking for workarounds: quantization to 4–8 bits, sparse transformers, mixtures of experts, liquid and spiking networks. Some approaches already deliver a 5–10x gain, but that is not enough to approach the biological level. So more attention is shifting to neuromorphic hardware.
Such systems already exist: SpiNNaker2 is deployed as a specialized supercomputer and can even be rented through the cloud, BrainChip Akida targets edge AI, and SynSense Xylo and Innatera Pulsar are aimed at microwatt-level and sensor scenarios. Even the best of these solutions still fall short of the brain by about three orders of magnitude in energy efficiency, and they require a completely different software stack.
The practical outlook is also sober. In 2026–2028, neuromorphic chips will most likely grow in robotics, industrial controllers, sensors and autonomous systems, where latency and power consumption are critical. Consumer electronics such as smartphones and watches, if they get such coprocessors at all, will do so closer to 2030 and later. The main brake is not only chip manufacturing but also software: familiar tools such as PyTorch and TensorFlow do not work with spiking networks without serious adaptation, and there is still no universal training standard for such systems.
The main takeaway is simple: the brain is not just smarter at certain tasks today, it is radically more economical as a computing machine. The next big leap in AI will therefore probably come not from an even larger LLM on an even bigger GPU cluster, but from a change in the underlying computing paradigm. For now, GPT-4 and its successors remain a very powerful but energy-expensive way to get intelligence-like behavior.
- Nov 2, 2026NVIDIA releases Nemotron 3.5 Bolt E4B: 4 GB and 133 tokens per second on an RTX 5070
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026MoneyGate safety layer blocked all 42 fraudulent requests to local AI models
- Nov 1, 2026ThinkJev Makes AI Think Only About Hard Questions: 28% Fewer Tokens
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.